> ## Documentation Index
> Fetch the complete documentation index at: https://anaconda.com/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Project assets
export const GCell = ({children, className}) =>
{children}
;
export const GTH = ({children, className}) =>
{children}
;
export const GRow = ({children}) => {children}
;
export const GBody = ({children}) => {children}
;
export const GHead = ({children}) => {children}
;
export const GTable = ({children, className, cols}) =>
{children}
;
[Metaflow artifacts](https://docs.metaflow.org/metaflow/basics#artifacts) are a core building block for managing data and models. Projects extend this concept with **data assets** and **model assets**, which complement artifacts by adding an extra layer of metadata, tracking, and observability, and unify the concept of Metaflow branching with the Git branches developers are used to.
## What are assets
Consider assets as **the core interfaces** of your projects: your key inputs, outputs, and pluggable components. Unlike code, which is versioned through systems like Git and rolled out with CI/CD, assets often evolve automatically. For example, data assets can refresh continuously via ETL pipelines, while models can be retrained and finetuned on a regular cadence through automated training workflows.
Asset tracking helps answer three key questions:
1. What are the core assets consumed and produced by the project?
2. Which project components (flows and deployments) are responsible
for producing and consuming each asset?
3. When was the asset last refreshed, and what are the key metrics
for its latest version?
These questions apply equally to models and data. The questions are also relevant both for traditional ML and bleeding-edge AI projects.
In the latter case, you might not retrain models continuously, though ongoing fine-tuning is certainly possible, but you are likely to experiment with different LLMs and upgrade them periodically. Crucially, assets are scoped to a project branch, allowing you to evaluate models and datasets in isolation across branches and compare their performance.
## Defining an asset
Every asset is defined through a configuration file, `asset_config.toml`, placed in a subdirectory under `model` and `data` in your [project structure](/docs/platform/guides/projects/project-structure).
For instance, you could define a `fraud` detection model, trained with financial `transaction` data, and a `churn` model trained with `product_events` as follows:
If `models/` or `data/` conflicts with existing folders in your project, you can customize these names via `[obproject_dirs]` in `obproject.toml`. See [Project structure](/docs/platform/guides/projects/project-structure#assets) for details.
A configuration field has a few mandatory fields, as shown by [the XKCD project example](https://github.com/outerbounds/ob-project-starter/blob/main/data/xkcd/asset_config.toml):
```toml theme={null}
name = "Latest XKCD comic"
id = 'xkcd'
description = "Latest xkcd comic strip image"
[properties]
key = "value"
test = "another"
```
* `name` is a human-readable name of the asset.
* `id` is an unambiguous ID used to refer to the asset.
* `description` is shown in the UI.
The resulting asset listing looks like this:
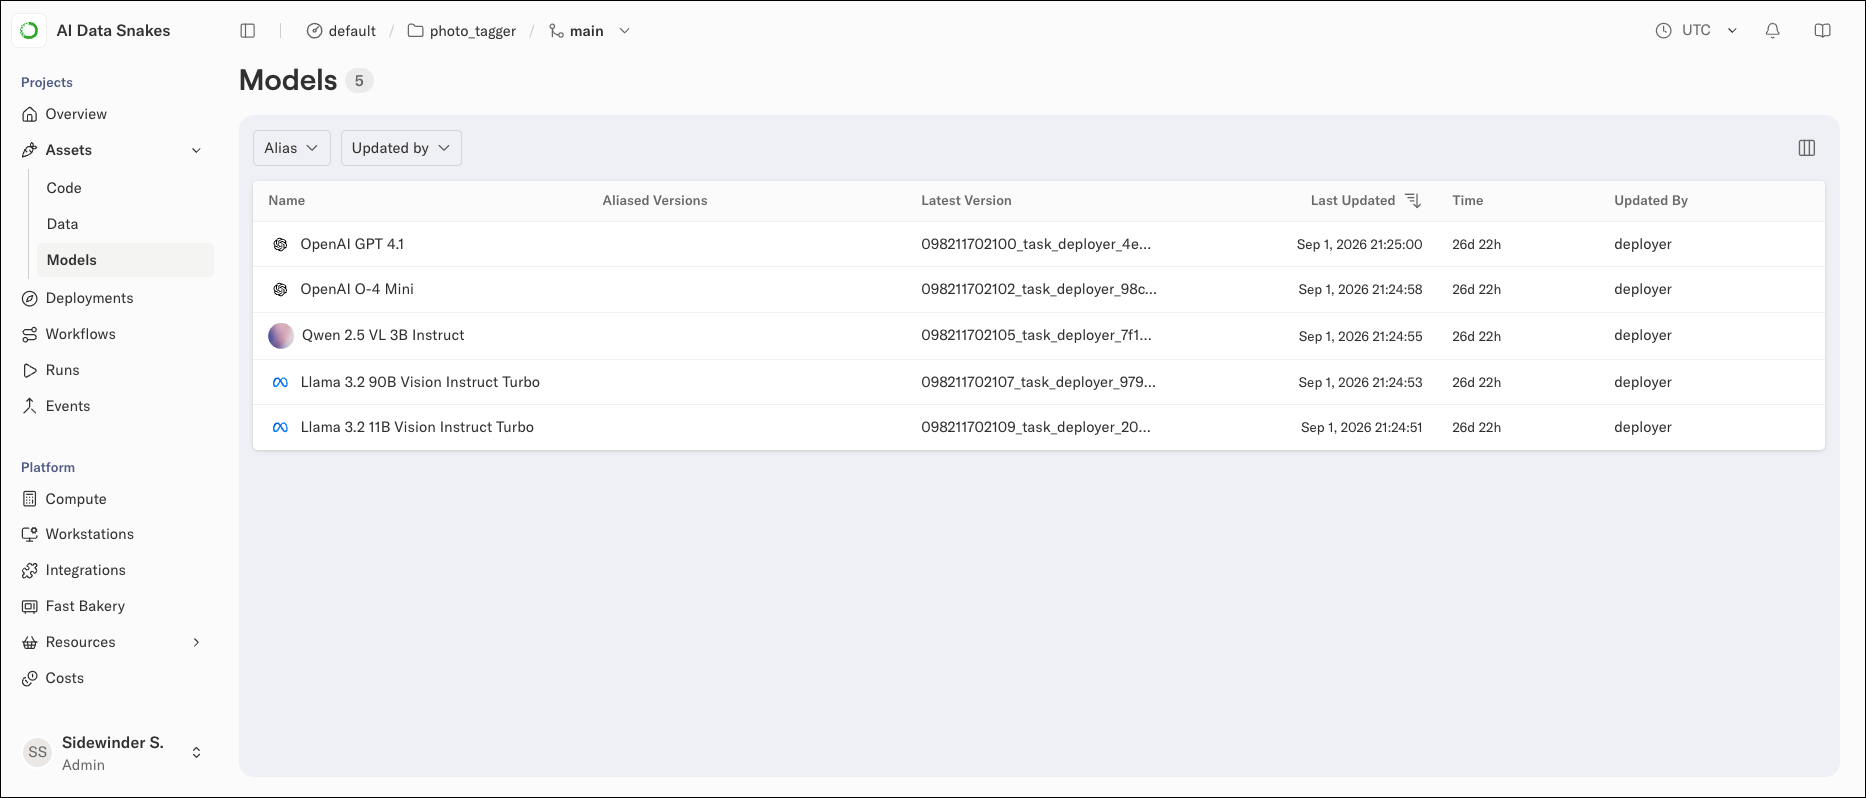 Optionally, you can assign arbitrary key-value pairs in the asset under `[properties]`. This can be handy, for instance, when working with models (LLMs) accessed through external inference providers, each of which has their own ID for the model:
```toml theme={null}
name = "Small LLama"
id = "small_llama"
description = "A small LLM, currently llama3.1 8B"
[properties]
bedrock = "us.meta.llama3-1-8b-instruct-v1:0"
nebius = "meta-llama/Meta-Llama-3.1-8B-Instruct-fast"
togetherai = "meta-llama/Meta-Llama-3.1-8B-Instruct-Turbo"
platform = "meta-llama/Llama-3.1-8B-Instruct"
```
You can access the properties programmatically through the Assets API. Asset definitions are updated automatically every time you push an update to the project through CI/CD.
## Updating an asset instance
Think of asset definitions as containers for **asset instances**. Every time an asset updates, a new versioned asset instance is created. It is possible to have an asset with no instances, just metadata, like references to external models as shown above, but in most cases you want to populate an asset programmatically.
Assets are typically updated in a flow, for instance, in an ETL workflow or a model retraining pipeline. The easiest way is to register an artifact, like `img_url` below, as an asset, as shown in [this snippet from `XKCDData`](https://github.com/outerbounds/ob-project-starter/blob/main/flows/xkcd-data/flow.py):
```python theme={null}
self.latest_id, self.img_url = fetch_latest()
self.prj.register_data("xkcd", "img_url")
```
**Assets are references.**
Assets are not used to store the data or model itself. Rather, they store a reference to the actual entity, such as a data artifact or an external model endpoint.
In `ob-project-starter`, the latest comic strip is a core entity being processed, so it makes sense to elevate the corresponding artifact as an asset. This allows you to observe the asset conveniently in the asset view:
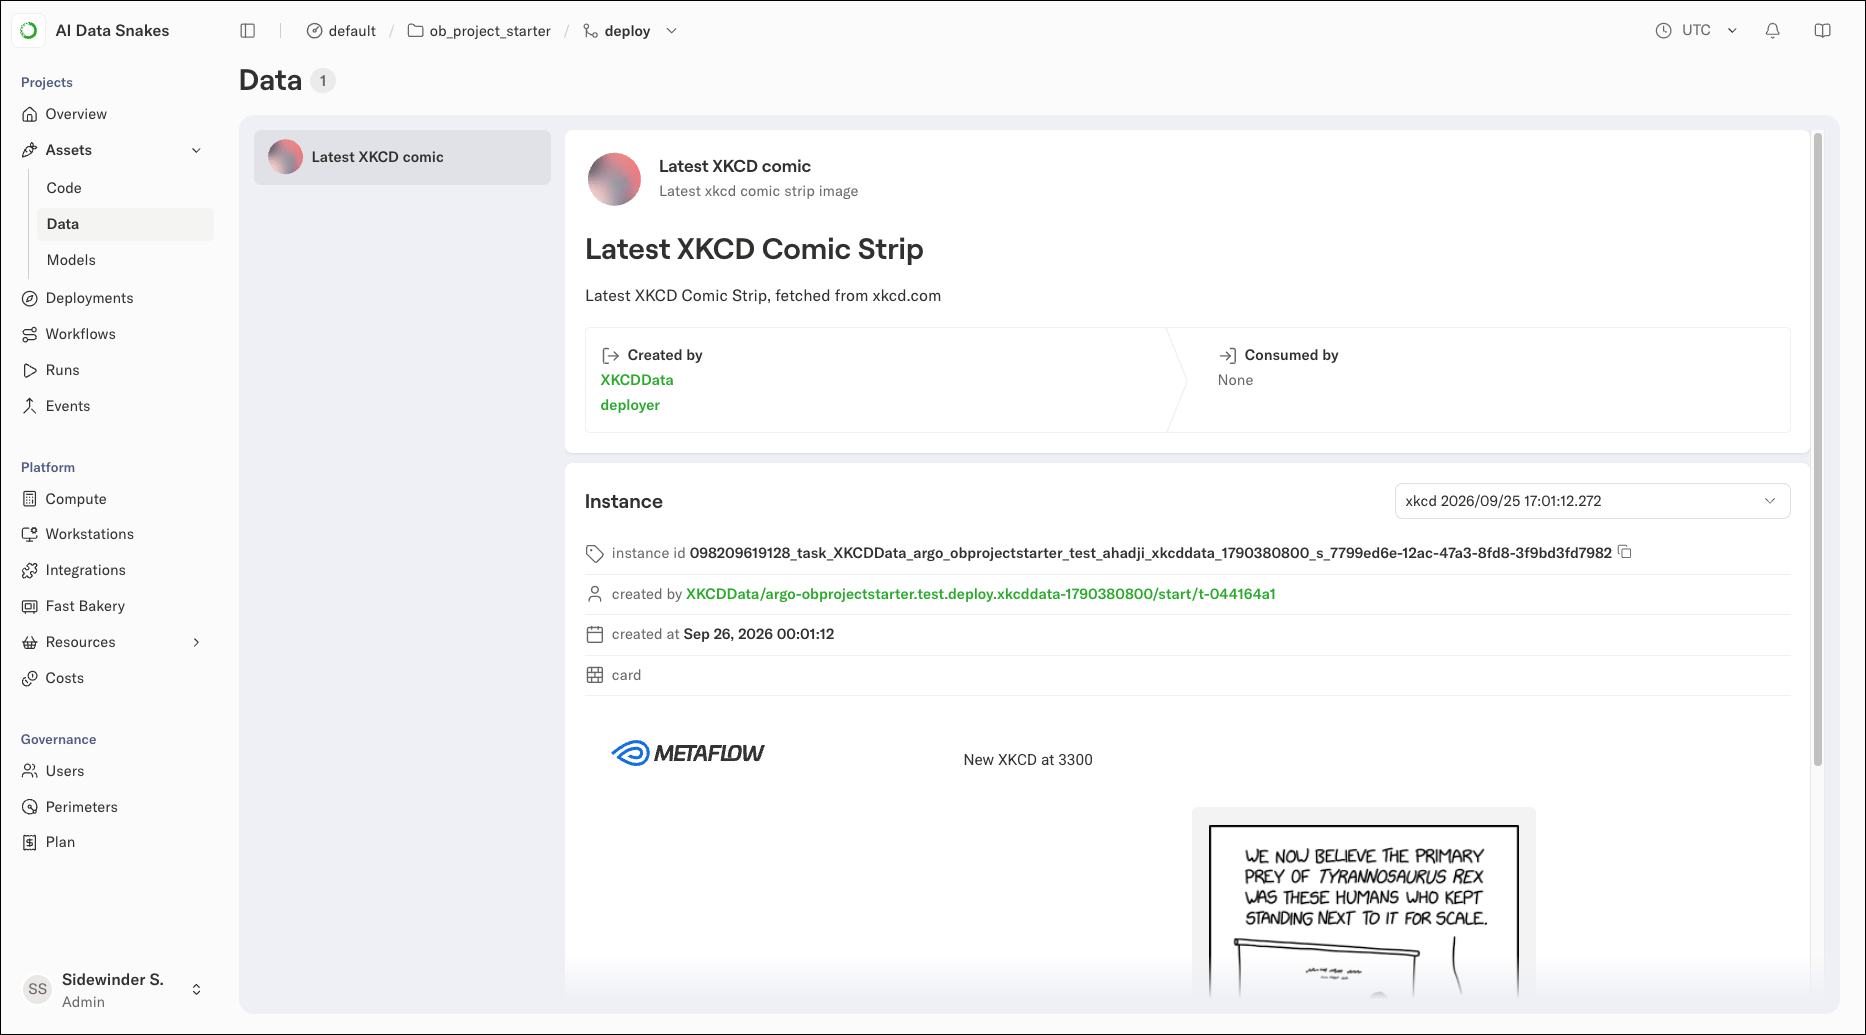 The visualization shown in the asset view is [a normal Metaflow `@card`](https://docs.metaflow.org/metaflow/visualizing-results), produced by the task registering an asset instance with `register_data`. Customize the card to show metrics that matter for the asset instance, for instance, data or model quality metrics.
Importantly, the asset UI contains a pointer to the exact task that produced each asset instance (by calling `register_data`), allowing you to **track data lineage** from producers to consumers.
### Asset metadata: properties, annotations, and tags
Assets support three types of metadata, each serving a different purpose:
Concept
Where defined
When set
Purpose
`properties`
`asset_config.toml`
Deploy time (static)
Metadata about the asset definition itself
`annotations`
`register_data()`
Runtime (per instance)
Instance-specific metadata like row counts and timestamps
`tags`
`register_data()`
Runtime (per instance)
Filtering and categorization
**Properties** are defined in `asset_config.toml` and are static; they describe the asset definition and don't change between instances. Use them for things like model provider IDs or data source descriptions.
**Annotations** are passed when registering an asset instance and are dynamic; they can vary with each instance. Use them for metrics like accuracy scores, row counts, or processing timestamps:
```python theme={null}
self.features = compute_features(data)
self.prj.register_data("fraud_features", "features",
annotations={"row_count": str(len(self.features)), "schema_version": "v2"})
```
**Tags** are also passed at registration time and are used for filtering and categorization:
```python theme={null}
self.prj.register_data("fraud_features", "features",
tags={"environment": "production", "source": "postgres"})
```
## Consuming assets
Using an asset is straightforward. In a task, call `get_data` for data assets or `get_model` for model assets:
```python theme={null}
# Retrieve data asset
self.img_url = self.prj.get_data("xkcd")
# Retrieve model asset
self.model = self.prj.get_model("fraud_classifier")
```
As shown in [the `XKCDExplainer` workflow](https://github.com/outerbounds/ob-project-starter/blob/main/flows/xkcd-explainer/flow.py), `get_data` fetches the latest instance of an asset and automatically resolves the reference to the corresponding data item. Similarly, `get_model` fetches the model artifact.
Importantly, both methods register the task as a consumer of the asset, contributing to data lineage tracking.
**External assets.**
`get_data()` and `get_model()` work for artifact-based assets registered with `register_data()` and `register_model()`. For external assets (S3 paths, checkpoints, HuggingFace models), use the low-level `prj.asset.consume_data_asset()` or `prj.asset.consume_model_asset()` methods, which return a reference containing the `blobs` list you can load manually.
### Asset branch resolution
**TL;DR: Deployed flows use git branches for assets. Local runs use Metaflow branches (user namespaces).** Use `[dev-assets]` to read production data while developing.
Assets are scoped to **branches**, with different resolution depending on context:
* **Deployed flows** (via CI/CD): Use git branches, providing a 1:1 mapping between your code branch and asset branch
* **Local runs** (`python flow.py run`): Use Metaflow branches (such as `user.alice`), providing user isolation
Context
Write branch
Read branch
Use case
Deployed from `main`
`main`
`main`
Self-contained production assets
Deployed from a feature branch
Feature branch
Feature branch
Isolated testing with its own assets
Deployed feature branch with `[dev-assets]`
Feature branch
`main`
Test new code against production data
Local run
`user.`
`user.`
Isolated local development
Local run with `[dev-assets]`
`user.`
`main`
Develop against production assets
The key pattern is **code promotion with data stability**: as code moves from a feature branch to main through CI/CD, assets are automatically scoped to the deployed branch.
The `[dev-assets]` configuration in `obproject.toml` enables the read-from-main patterns above:
```toml theme={null}
project = "my_project"
[dev-assets]
branch = "main" # Read assets from the main branch
```
This allows you to:
* **Develop locally** against production assets without affecting them
* **Deploy feature branches** that validate new code against real data
* **Iterate safely** before merging changes to main
**Local vs Deployed branch resolution.**
Local runs use Metaflow's `@project` branch (such as `user.alice`) for asset isolation, ensuring local experiments don't interfere with deployed flows. Deployed flows use git branches, captured at deploy time via `obproject-deploy`.
### Deleting individual assets
Asset names are not reusable in place; a rename creates a new asset and orphans the old name in the catalog. Prune orphans from a flow step:
```python theme={null}
self.prj.asset.delete_data_asset("old_name")
self.prj.asset.delete_model_asset("old_model_name")
```
The call automatically removes the asset from both stores it lives in: the catalog (instances + lineage) and the project's flowproject metadata (declaration list, what the UI Overview reads). It returns a `DeleteResult(catalog_deleted, metadata_updated)`, so that callers can tell whether anything actually changed. Idempotent reruns return `(False, False)`. Deletion is irreversible; the catalog has no deprecate or hide state.
To mark an asset superseded without removing it, tag a new instance, for instance, `tags={"status": "deprecated"}`, and have consumers filter via `list_data_assets(tags=...)`. See [`prj.asset.delete_data_asset()`](/docs/platform/guides/projects/utilities-api/assets/deletion/delete-data-asset) for the full spec.
The same methods are available from a standalone script (admin tools, CI cleanup, notebooks) by constructing `Asset` directly with an explicit `entity_ref`:
```python theme={null}
from obproject.assets import Asset
asset = Asset(
project="my-project",
branch="main",
entity_ref={"entity_kind": "user", "entity_id": "cleanup-script"},
)
asset.delete_data_asset("obsolete_dataset")
```
See [Standalone Asset Usage](/docs/platform/guides/projects/utilities-api/assets/standalone-usage) for the full constructor reference.
### What happens when a branch is deleted
When a feature branch is torn down with `teardown-branch`, its asset metadata is deleted. The underlying data and model weights in S3 persist, but the catalog entries pointing to them are gone. If you trained a model on a feature branch and want it available on `main`, use `promote_assets()` before teardown to copy the metadata pointers across branches. See [Promoting assets before teardown](/docs/platform/guides/projects/project-lifecycle#promoting-assets-before-teardown) for details and CI/CD integration.