> ## Documentation Index
> Fetch the complete documentation index at: https://anaconda.com/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Using cost reports
The cost reports on the platform help you understand and optimize your compute costs. This page assumes you are familiar with the [Overview of cost optimization](/docs/platform/guides/monitor/cost-optimization-overview); read it first if you have not.
To view the cost reports, select **Costs** in the left-hand navigation. The reports are organized into three views: **Historical spend**, **Nodes**, and **Flows**. Click a view to open it.
Cost reports become available 24 to 48 hours after you start using the platform.
## Historical spend
The **Historical spend** view shows an estimate of compute costs incurred by the platform over the past 30 days:
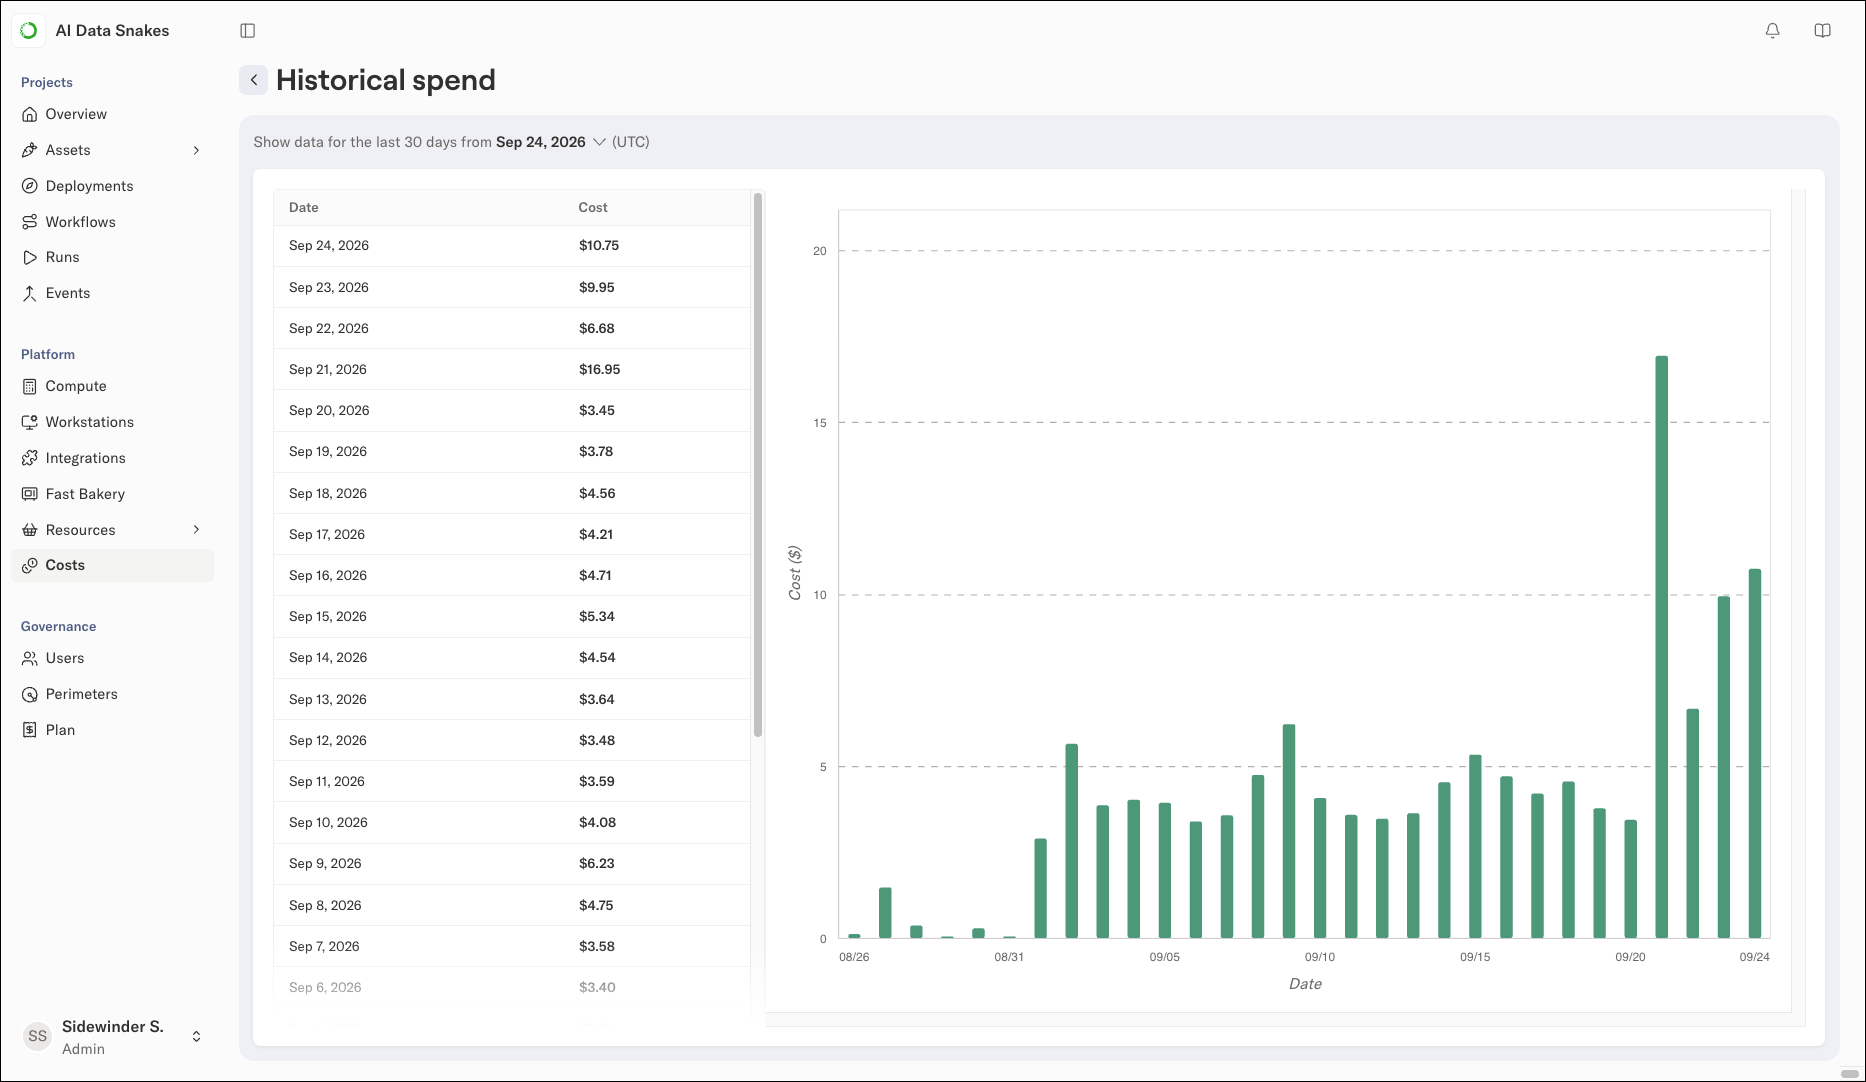 Use this view to get a quick overview of whether costs are within the expected range and to decide if further optimization is needed. If costs are within an acceptable range, you do not need to do anything else.
The view updates daily. Use the date picker to choose the end date of the 30-day window.
Note the following about the cost estimate:
* The dollar amounts are based on the cloud's on-demand list pricing, not your negotiated pricing. The amounts do not include discounts such as reserved instances or savings plans, so your actual compute costs are likely lower.
* The amounts indicate the variable cost component driven by compute on the platform. They do not include the platform's total cost, which also includes data storage and database costs. Data costs are typically small compared to compute costs and grow slowly relative to the number of workloads.
* All amounts are quoted in US dollars, even if your account is set to use another currency.
## Instance usage
To understand the daily costs shown in the historical view in detail, open the **Nodes** view and use the date picker to choose a day, such as a day with a cost spike in the historical view.
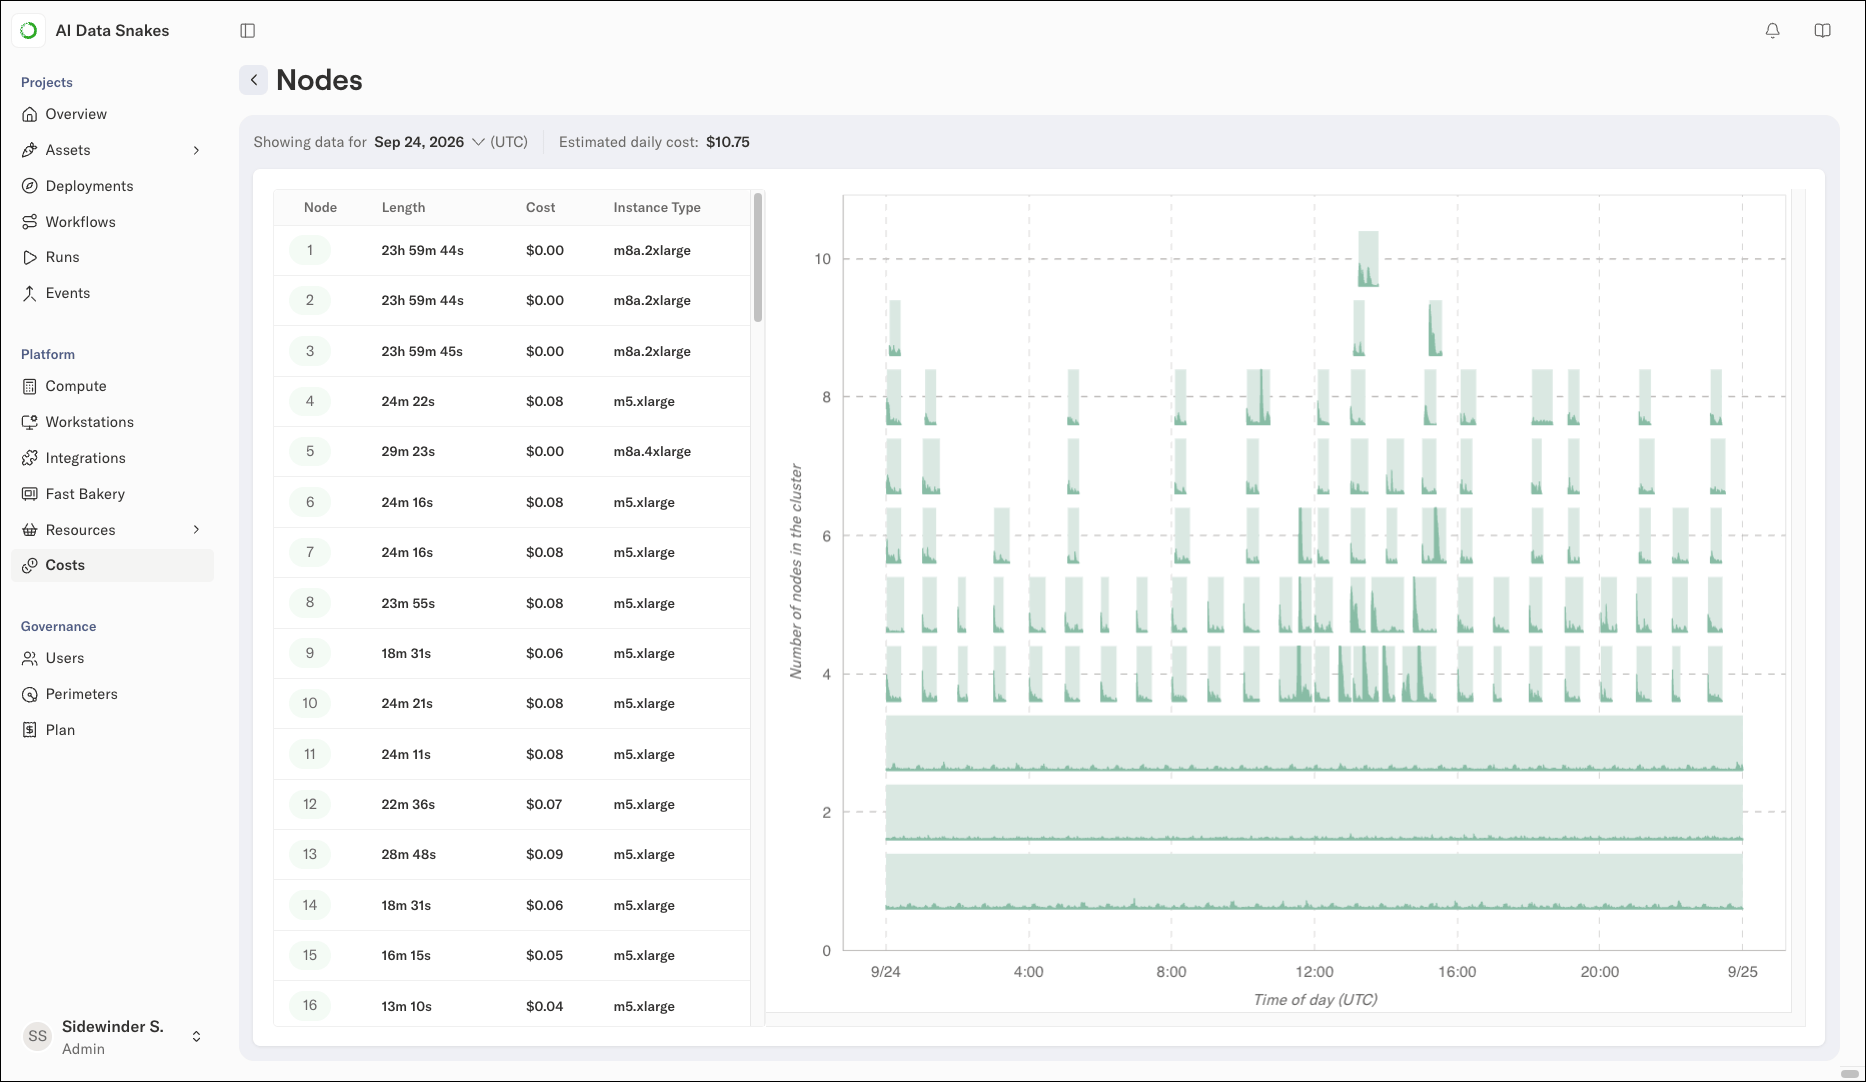 The table on the left lists the instances that ran that day, with each instance's duration, cost, and type. The estimated daily cost at the top matches the amount shown in the historical view for that day.
On the right, a timeline chart shows the number of nodes in the cluster over the day, with each instance's span showing its utilization over time. In the screenshot above, three `m8a.2xlarge` instances ran for most of the day and account for most of the daily cost, while shorter-lived instances came and went as demand changed.
### Why an instance was provisioned
A natural follow-up question is why the instance was provisioned. Click an instance's span or its entry in the list to open a detailed view showing the steps and workstations assigned to the instance.
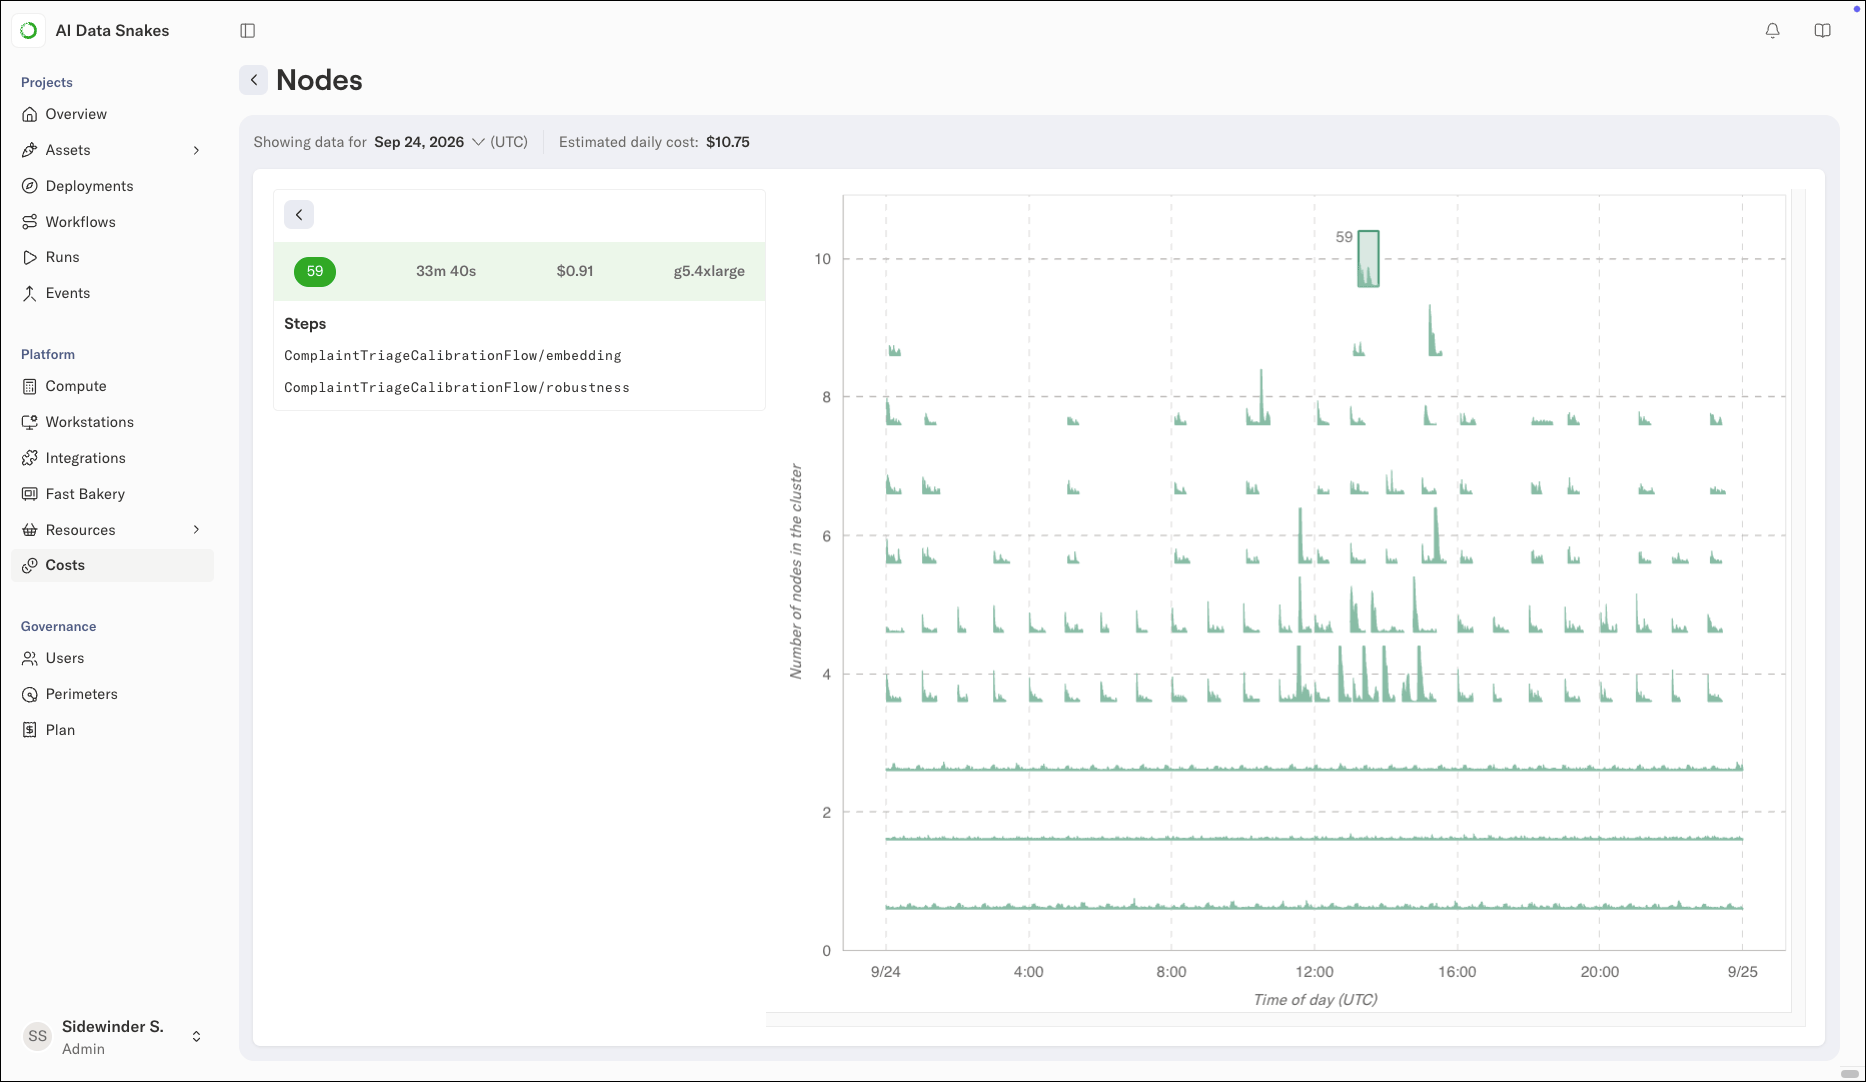 In this case, the instance is a `g5.4xlarge` GPU instance that ran for about half an hour, provisioned for the `embedding` and `robustness` steps of `ComplaintTriageCalibrationFlow`.
## Resource utilization
To check whether tasks are [using their requested resources efficiently](/docs/platform/guides/monitor/cost-optimization-overview#right-sizing-resource-requests), open the **Flows** view. This view shows resource utilization for each step in your flows.
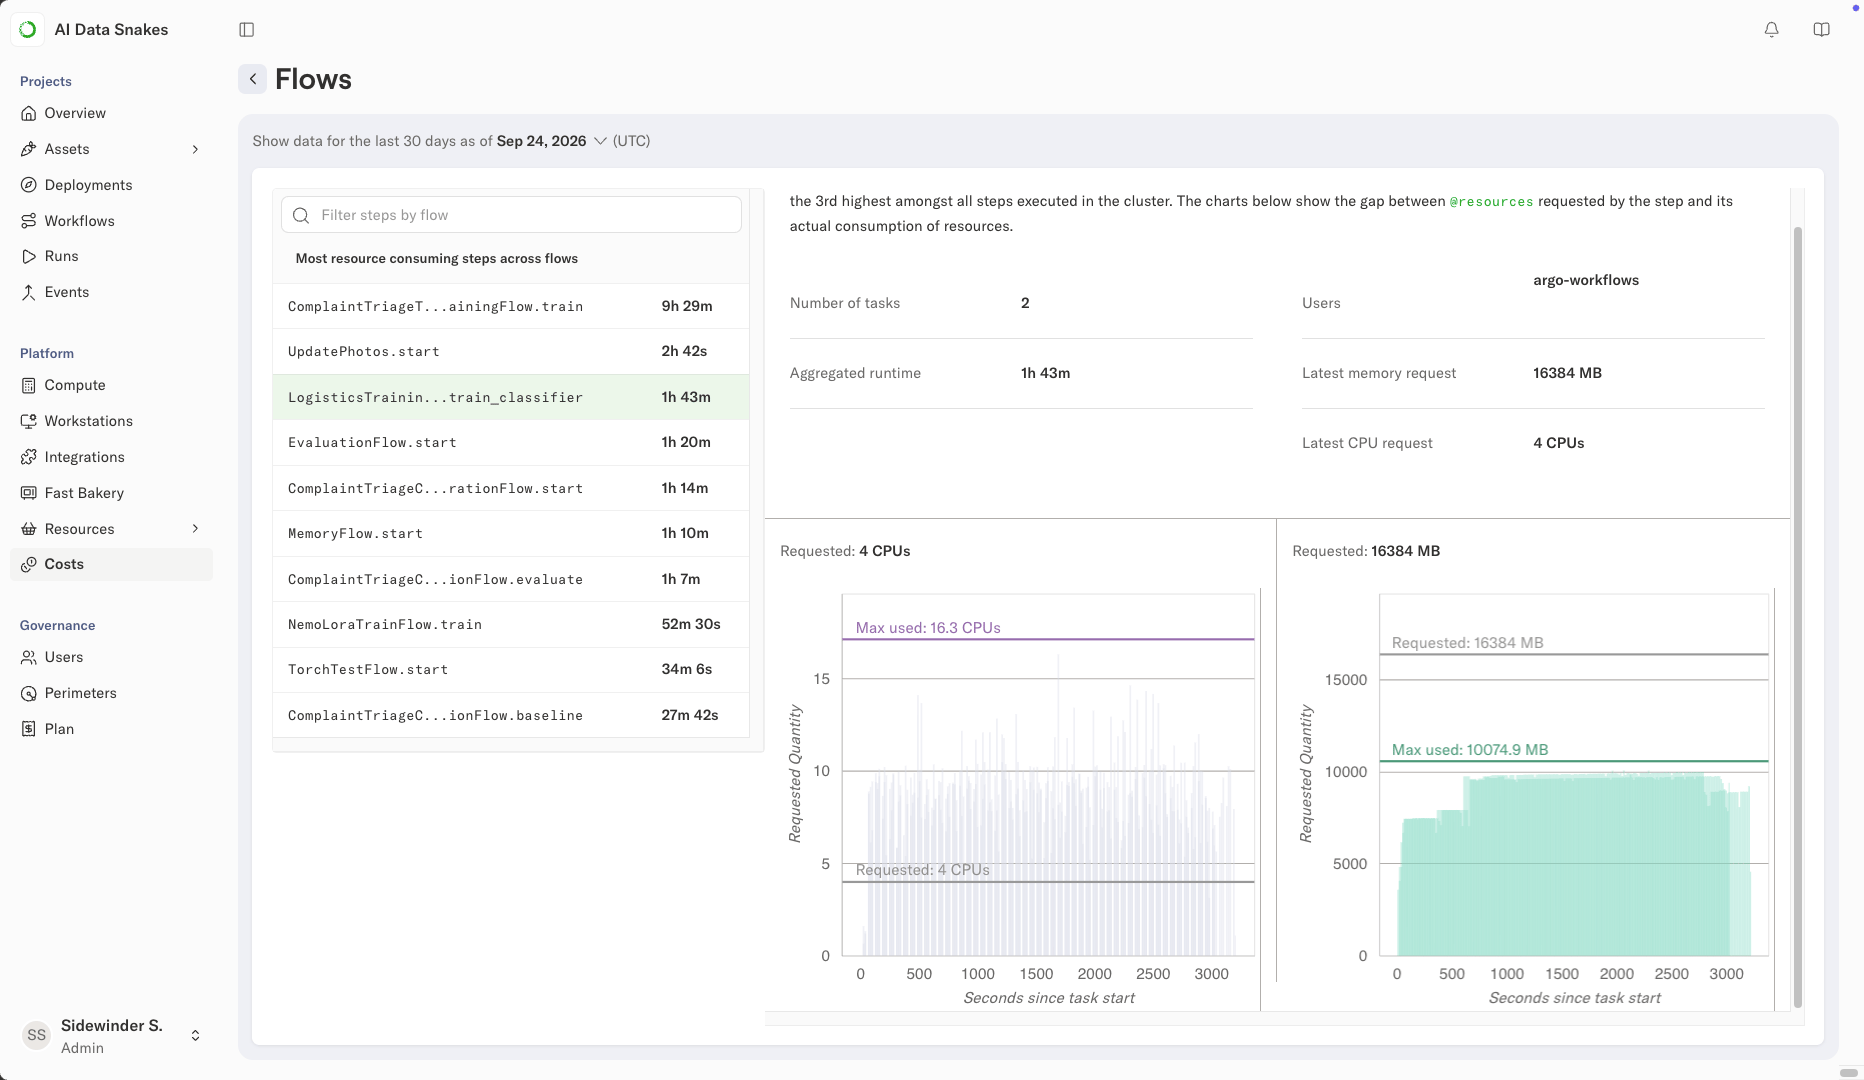 The list on the left, **Most resource consuming steps across flows**, shows the steps with the highest total runtime over the reporting window, which are typically the highest cost drivers and natural targets for optimization. Use the **Filter steps by flow** field to narrow the list to a specific flow. Select a step to see its resource utilization charts.
On the right, charts show the selected step's resource utilization. Note the following about the charts:
* One chart shows CPU utilization and the other shows memory utilization.
* The X axis shows seconds since the task started. A task often exhibits distinct behavior during its lifetime, such as higher memory consumption after data has been loaded.
* The charts **aggregate resource consumption** for the selected step over the past 30 days, so you see multiple time series overlaid. This shows the overall behavior while also revealing outliers.
* A gray horizontal bar shows the amount of CPU or memory requested through the `@resources` decorator. A second bar shows the maximum resources used when it differs from the amount requested.
In the screenshot above, the step requested four CPUs, but its tasks used up to 16.3 CPUs at peak. Tasks that use more than they request contend for CPU time and run slower, so increasing the CPU request would let them run at full speed. The step's memory usage peaks at about 10GB against the requested 16GB, leaving room to reduce the memory request as well.
### Observing resource utilization in real time
The cost reporting views aggregate information over longer periods and update daily. Anaconda recommends against optimizing resource requirements based on a single data point, especially for tasks that consume changing data.
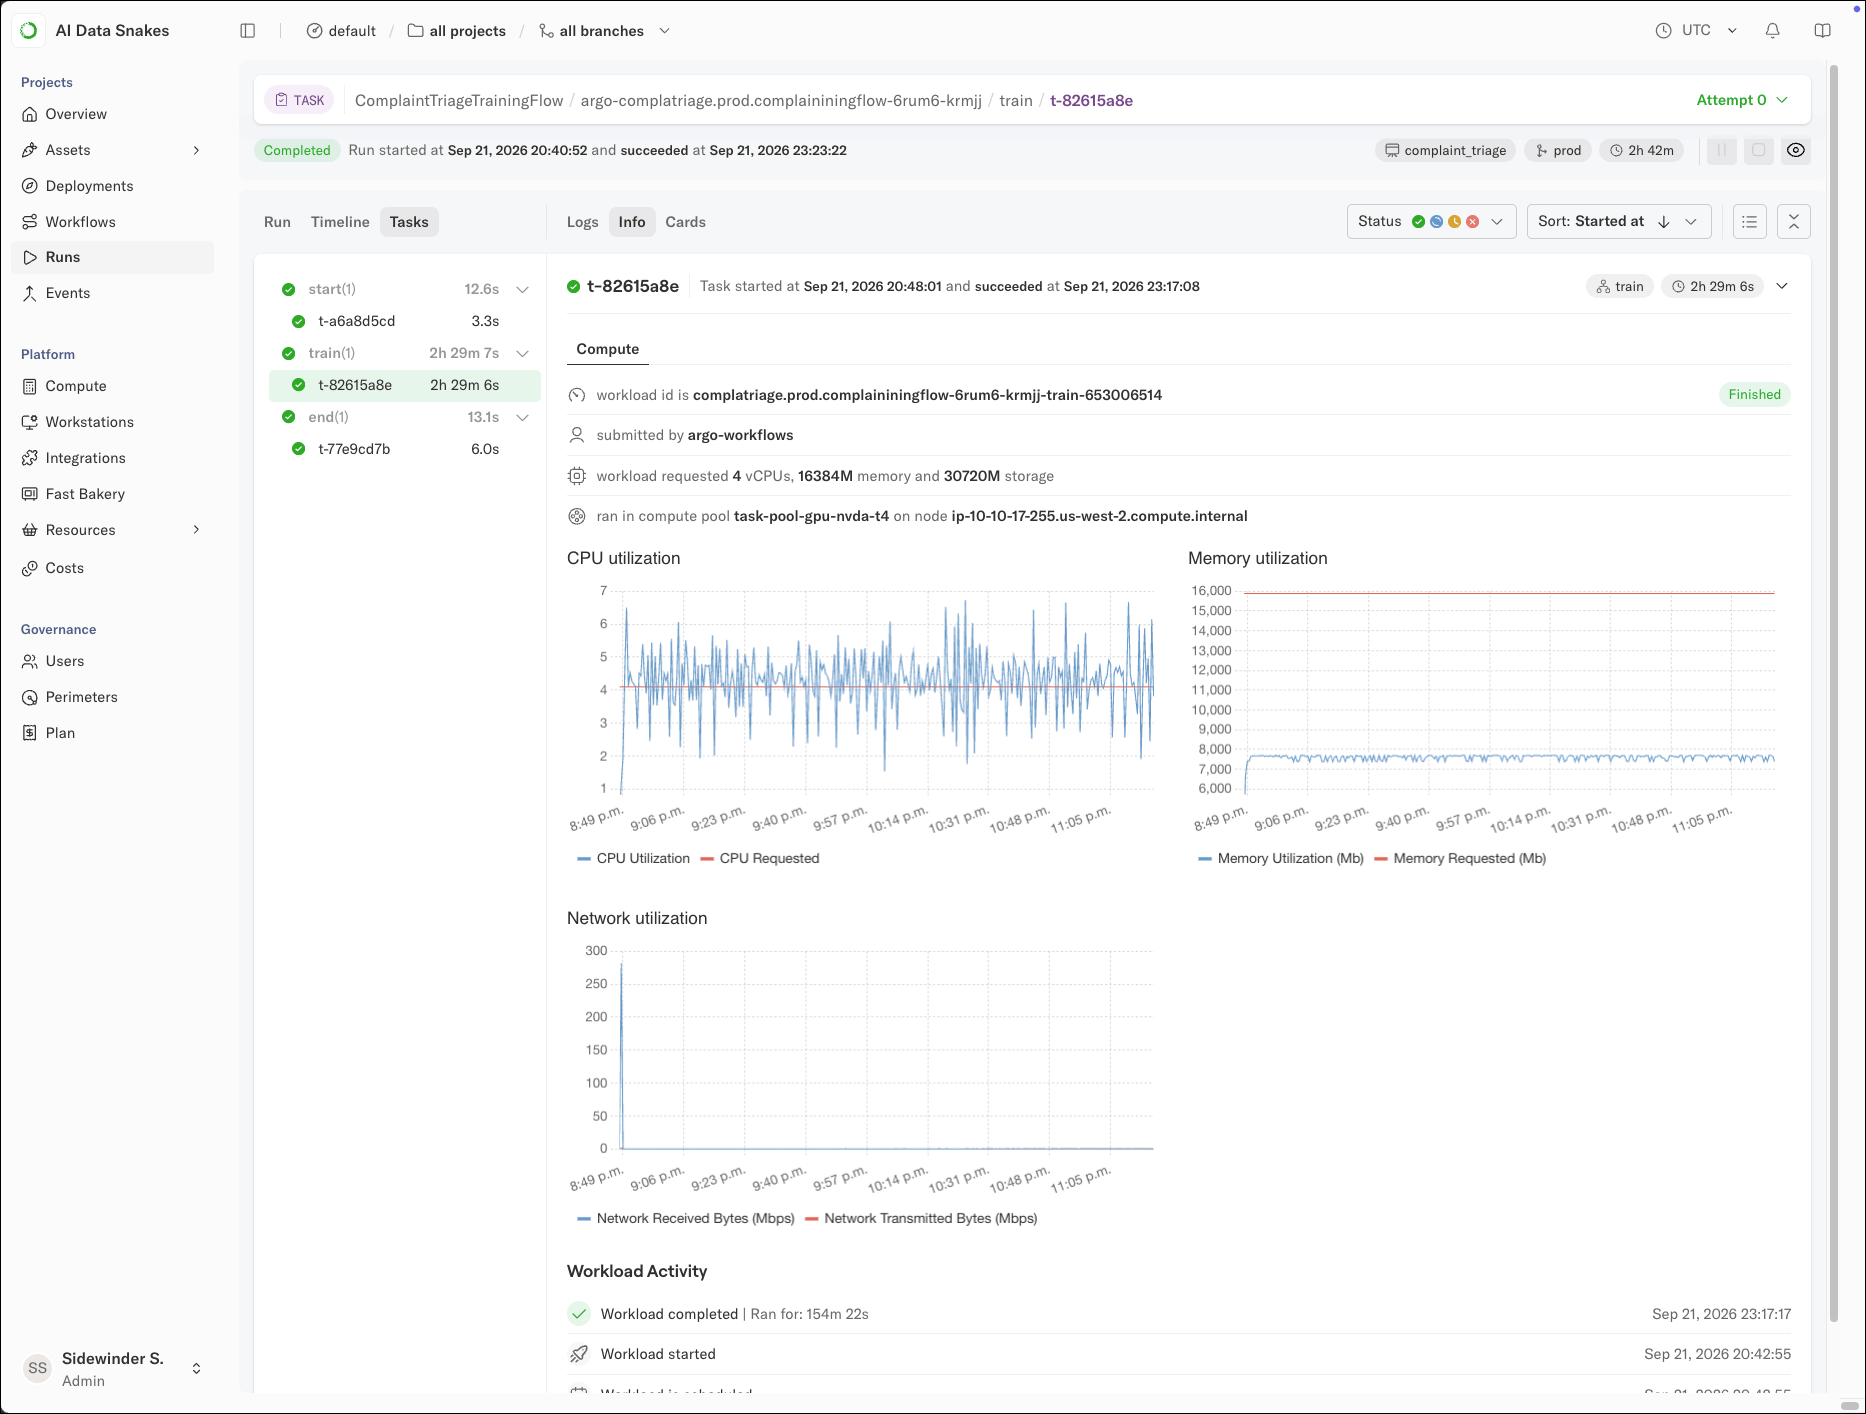
During development, however, it is useful to check whether resource requirements are in the right ballpark. You can see resource usage in real time while a run executes: select the run in the **Runs** view, select a task, and scroll to the **Compute** section, which shows CPU, memory, and network utilization charts:
 Utilization charts are only available for tasks that execute for longer than one minute.
In the screenshot above, the task requested four CPUs (the red line) and regularly burst above six CPUs (the blue line) during execution. Brief excursions above the request are normal for bursty workloads, so there is no need to chase every spike with a larger request.
Memory consumption, by contrast, stays flat around 7.5GB against a requested 16GB. This task is a candidate for a lower memory request, but check the aggregated cost report before right-sizing: a single task might not show the peak usage of every run.
**Don't set resources too low.**
A downside of setting `@resources` too low, especially for `memory`, is that the task might crash with an Out-Of-Memory error, which is generally worse than slight underutilization.
### Identifying resource underutilization
This example highlights a case of resource underutilization:
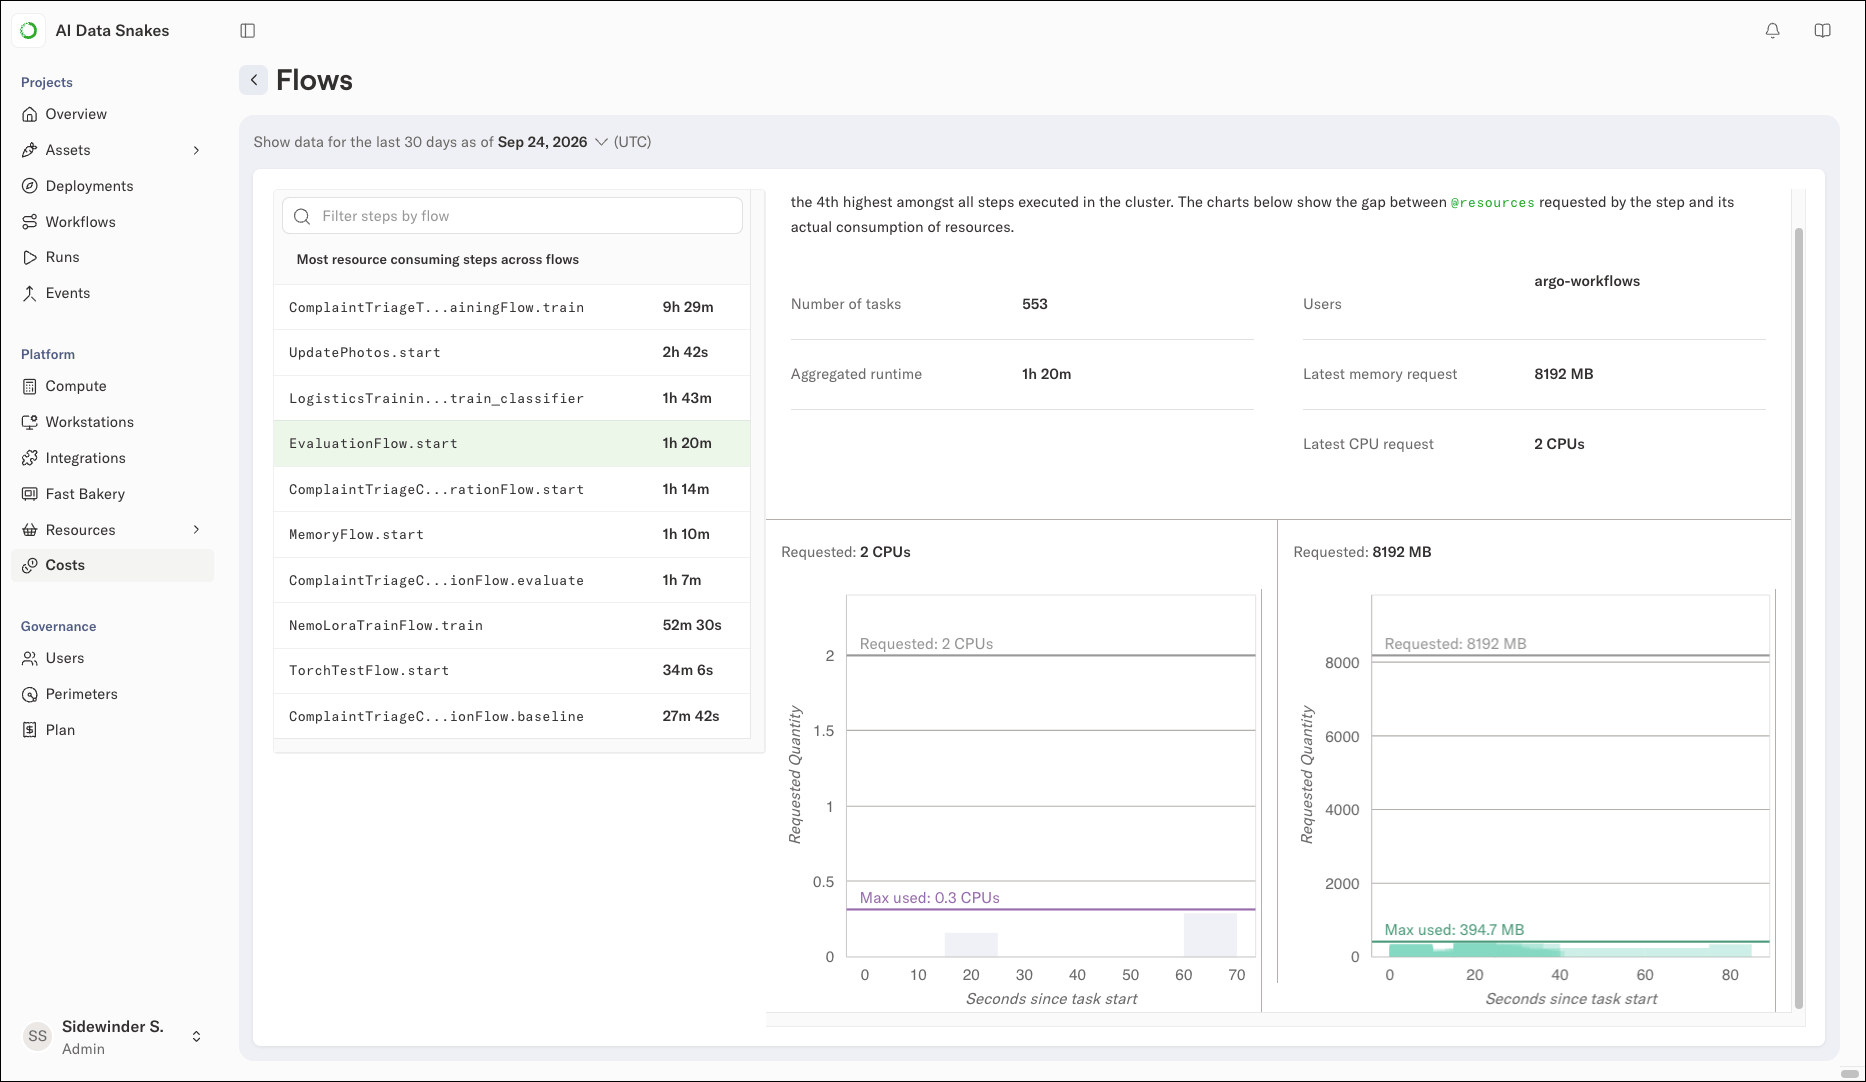 The step requests two CPUs, but its tasks never use more than about 0.3 CPUs. Similarly, it requests 8GB of memory but peaks below 400MB. You could right-size this step to `@resources(cpu=1, memory=2000)` without an adverse effect. This frees resources on the instance, allowing other tasks to be scheduled simultaneously, which increases utilization and lowers total compute costs.
**Why doesn't the system optimize `@resources` automatically?**
Resource consumption is typically a function of input data, which might grow or shrink over time. The platform surfaces the utilization data, but right-sizing decisions rely on your understanding of the data and use cases.