> ## Documentation Index
> Fetch the complete documentation index at: https://anaconda.com/docs/llms.txt
> Use this file to discover all available pages before exploring further.
# Model servers
export const Comments = ({children}) => {
return ;
};
export const TroubleshootSolution = ({children}) => <>
Solution
{children}
;
export const TroubleshootCause = ({children}) =>
Cause
{children}
;
export const TroubleshootTitle = ({children}) => <>
{children}
;
export const Troubleshoot = ({children}) => ;
Model servers let you run open-source large language models (LLMs) locally on your own machine and interact with them through API calls. You can create multiple named servers, each configured with its own model, address, port, API key, and model settings. This makes it easy to test different models or configurations in parallel without affecting other servers.
Prefer working on the command line? Use the [Anaconda AI CLI](/docs/cli-reference/anaconda-ai/getting-started) to manage your servers.
## Creating a server
Model servers are the core component of Anaconda Desktop that enable you to interact with your locally downloaded LLMs through API calls. Follow these steps to create and configure your servers:
Select **Model Servers** from the left-hand navigation.
Click **Create Server** in the top-right corner.
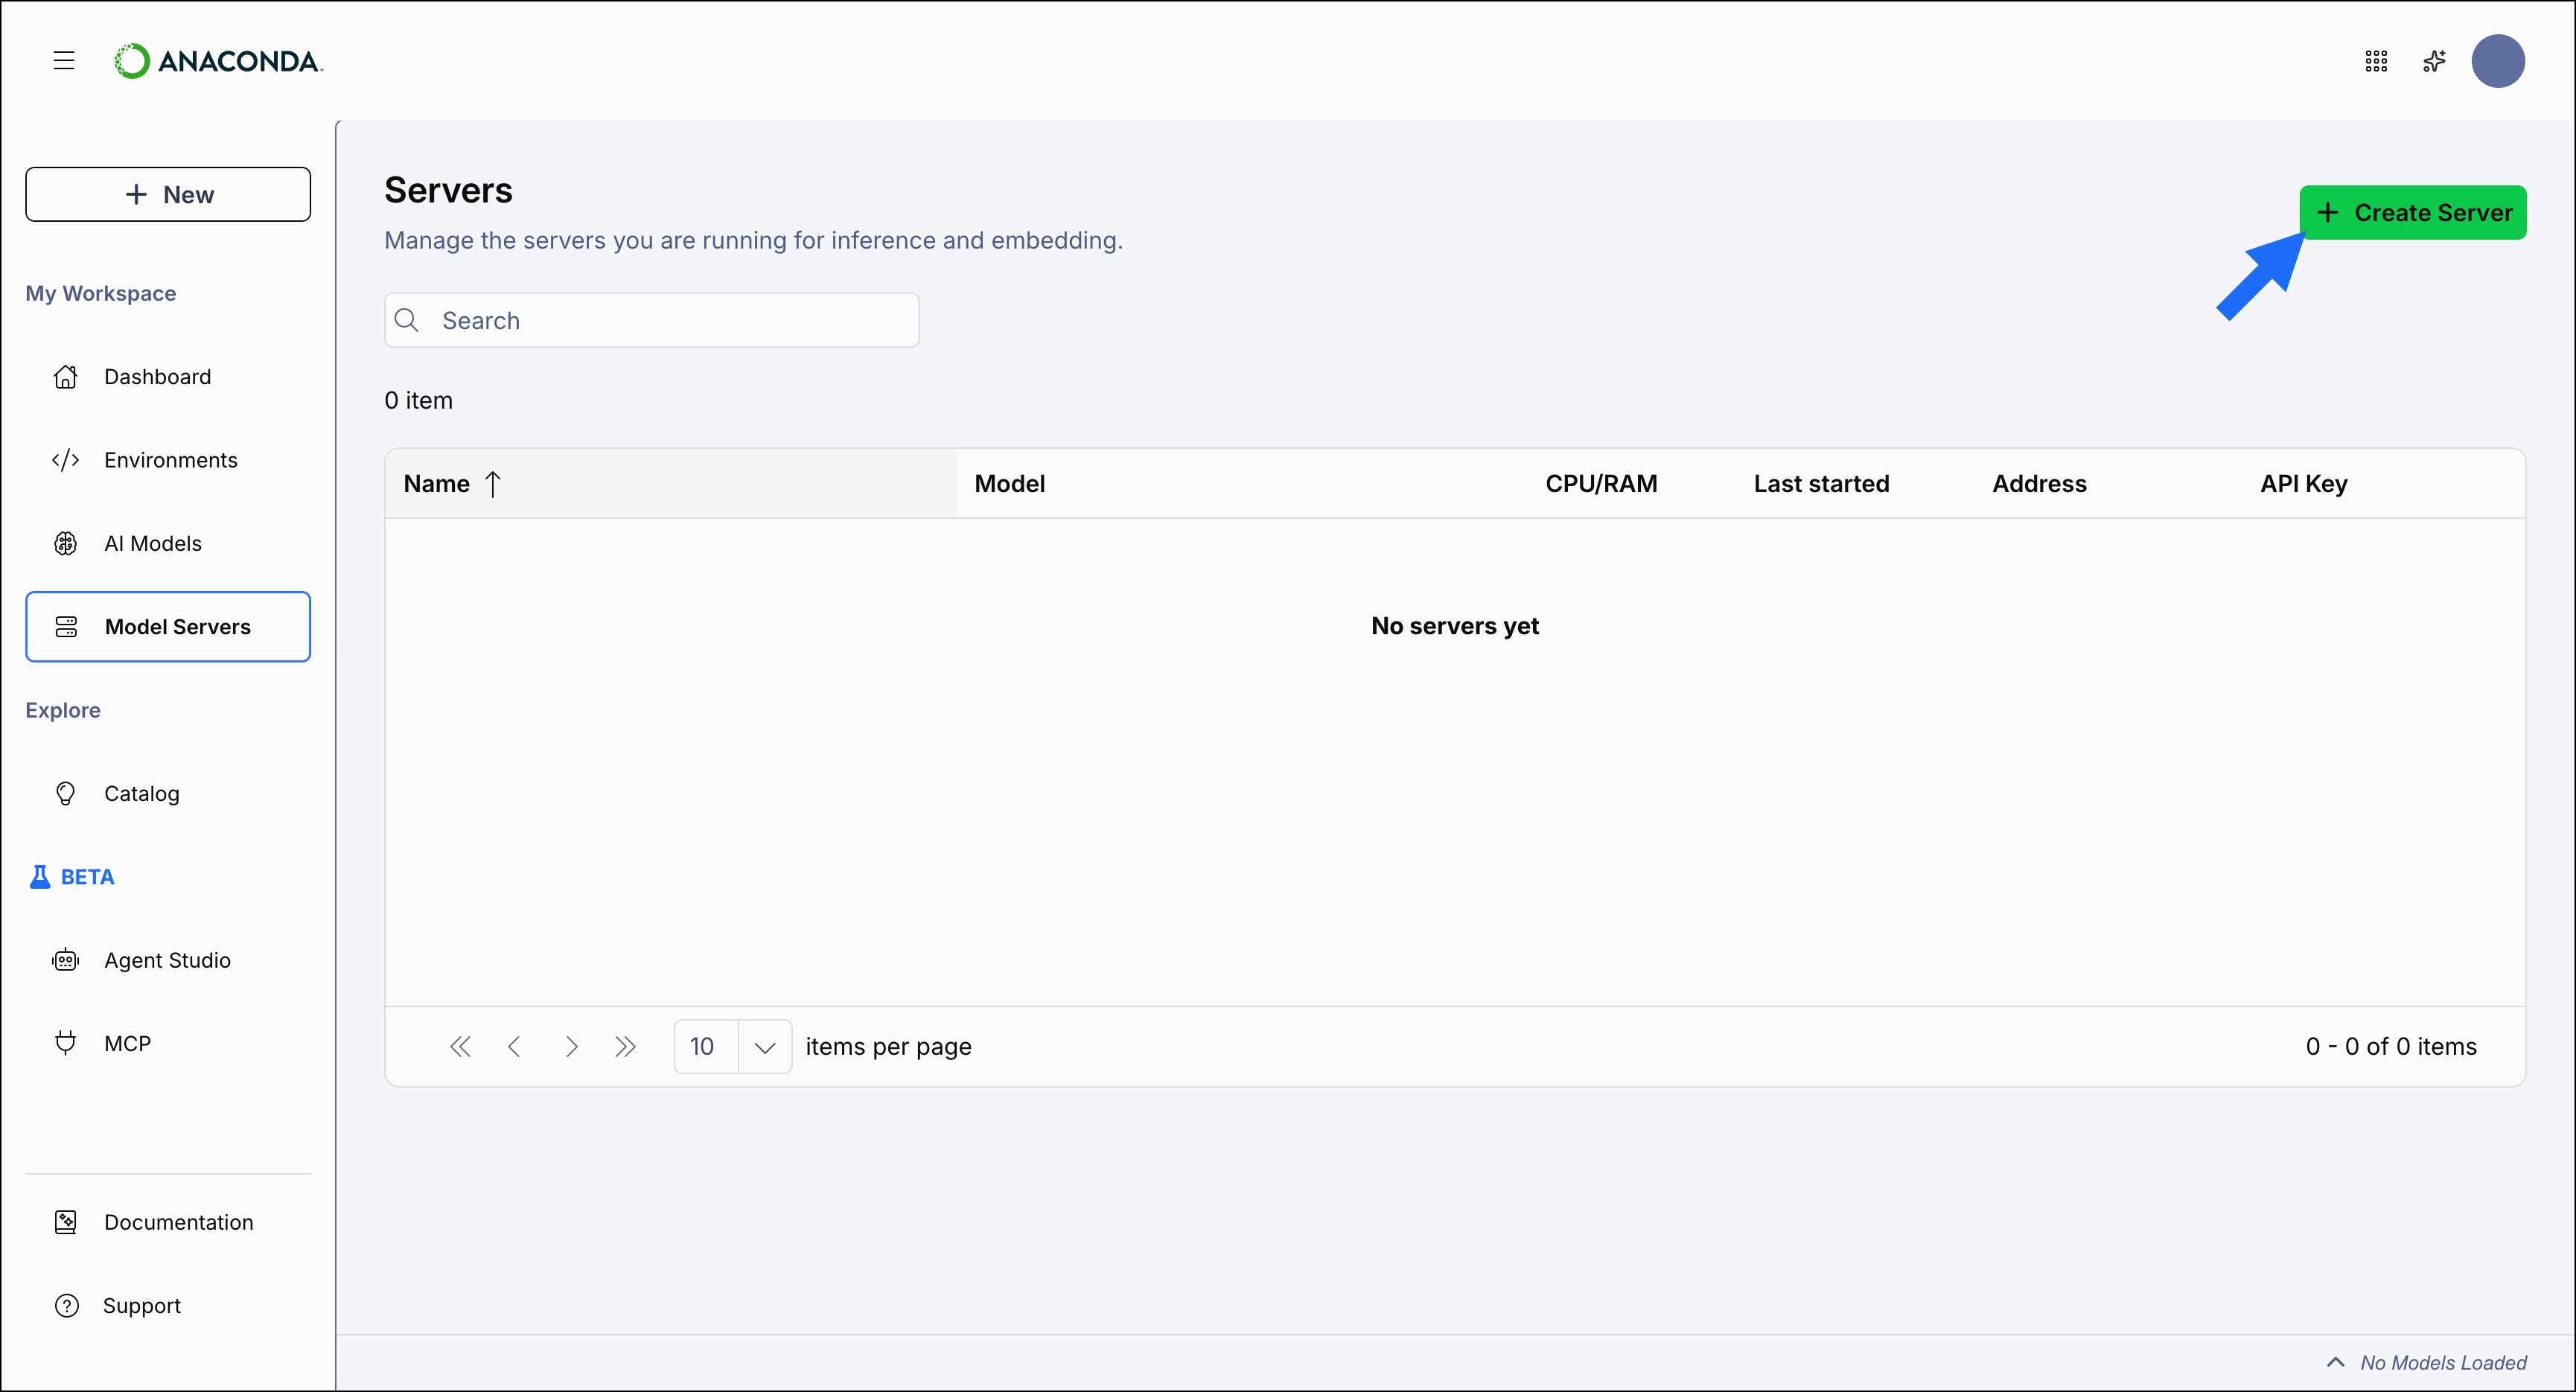 Fill in the fields in the **Create Server** dialog:
* **Server Name**: A unique name to identify this server.
* **Address**: The network address to bind to (default: `127.0.0.1`).
* **Port**: The port to listen on (default: `8080`).
* **API Key** (optional): A string used to authenticate requests. See [API key](#api-key) for details.
* **Model Name**: Select the model and quantization level to load.
* **Maximum Response Length**: The maximum number of tokens the model generates in a single response (0–2,048). Check **Let the model decide** to let the model determine when it has fulfilled the request.
* **Context Length**: The maximum number of tokens the model can hold in memory at once, including the conversation history and the response being generated (0–8,192).
* **Temperature**: Controls the randomness of the model's output (0–1). Lower values produce more deterministic responses; higher values produce more varied output.
* **System Prompt**: Instructions that shape the model's behavior for every request.
* **Enable vision (multimodal)**: Appears only when an `image-text-to-text` model is selected. When checked, the server starts with the downloaded multimodal projector (the model's vision component), enabling vision capabilities. When unchecked, the model runs in text-only mode.
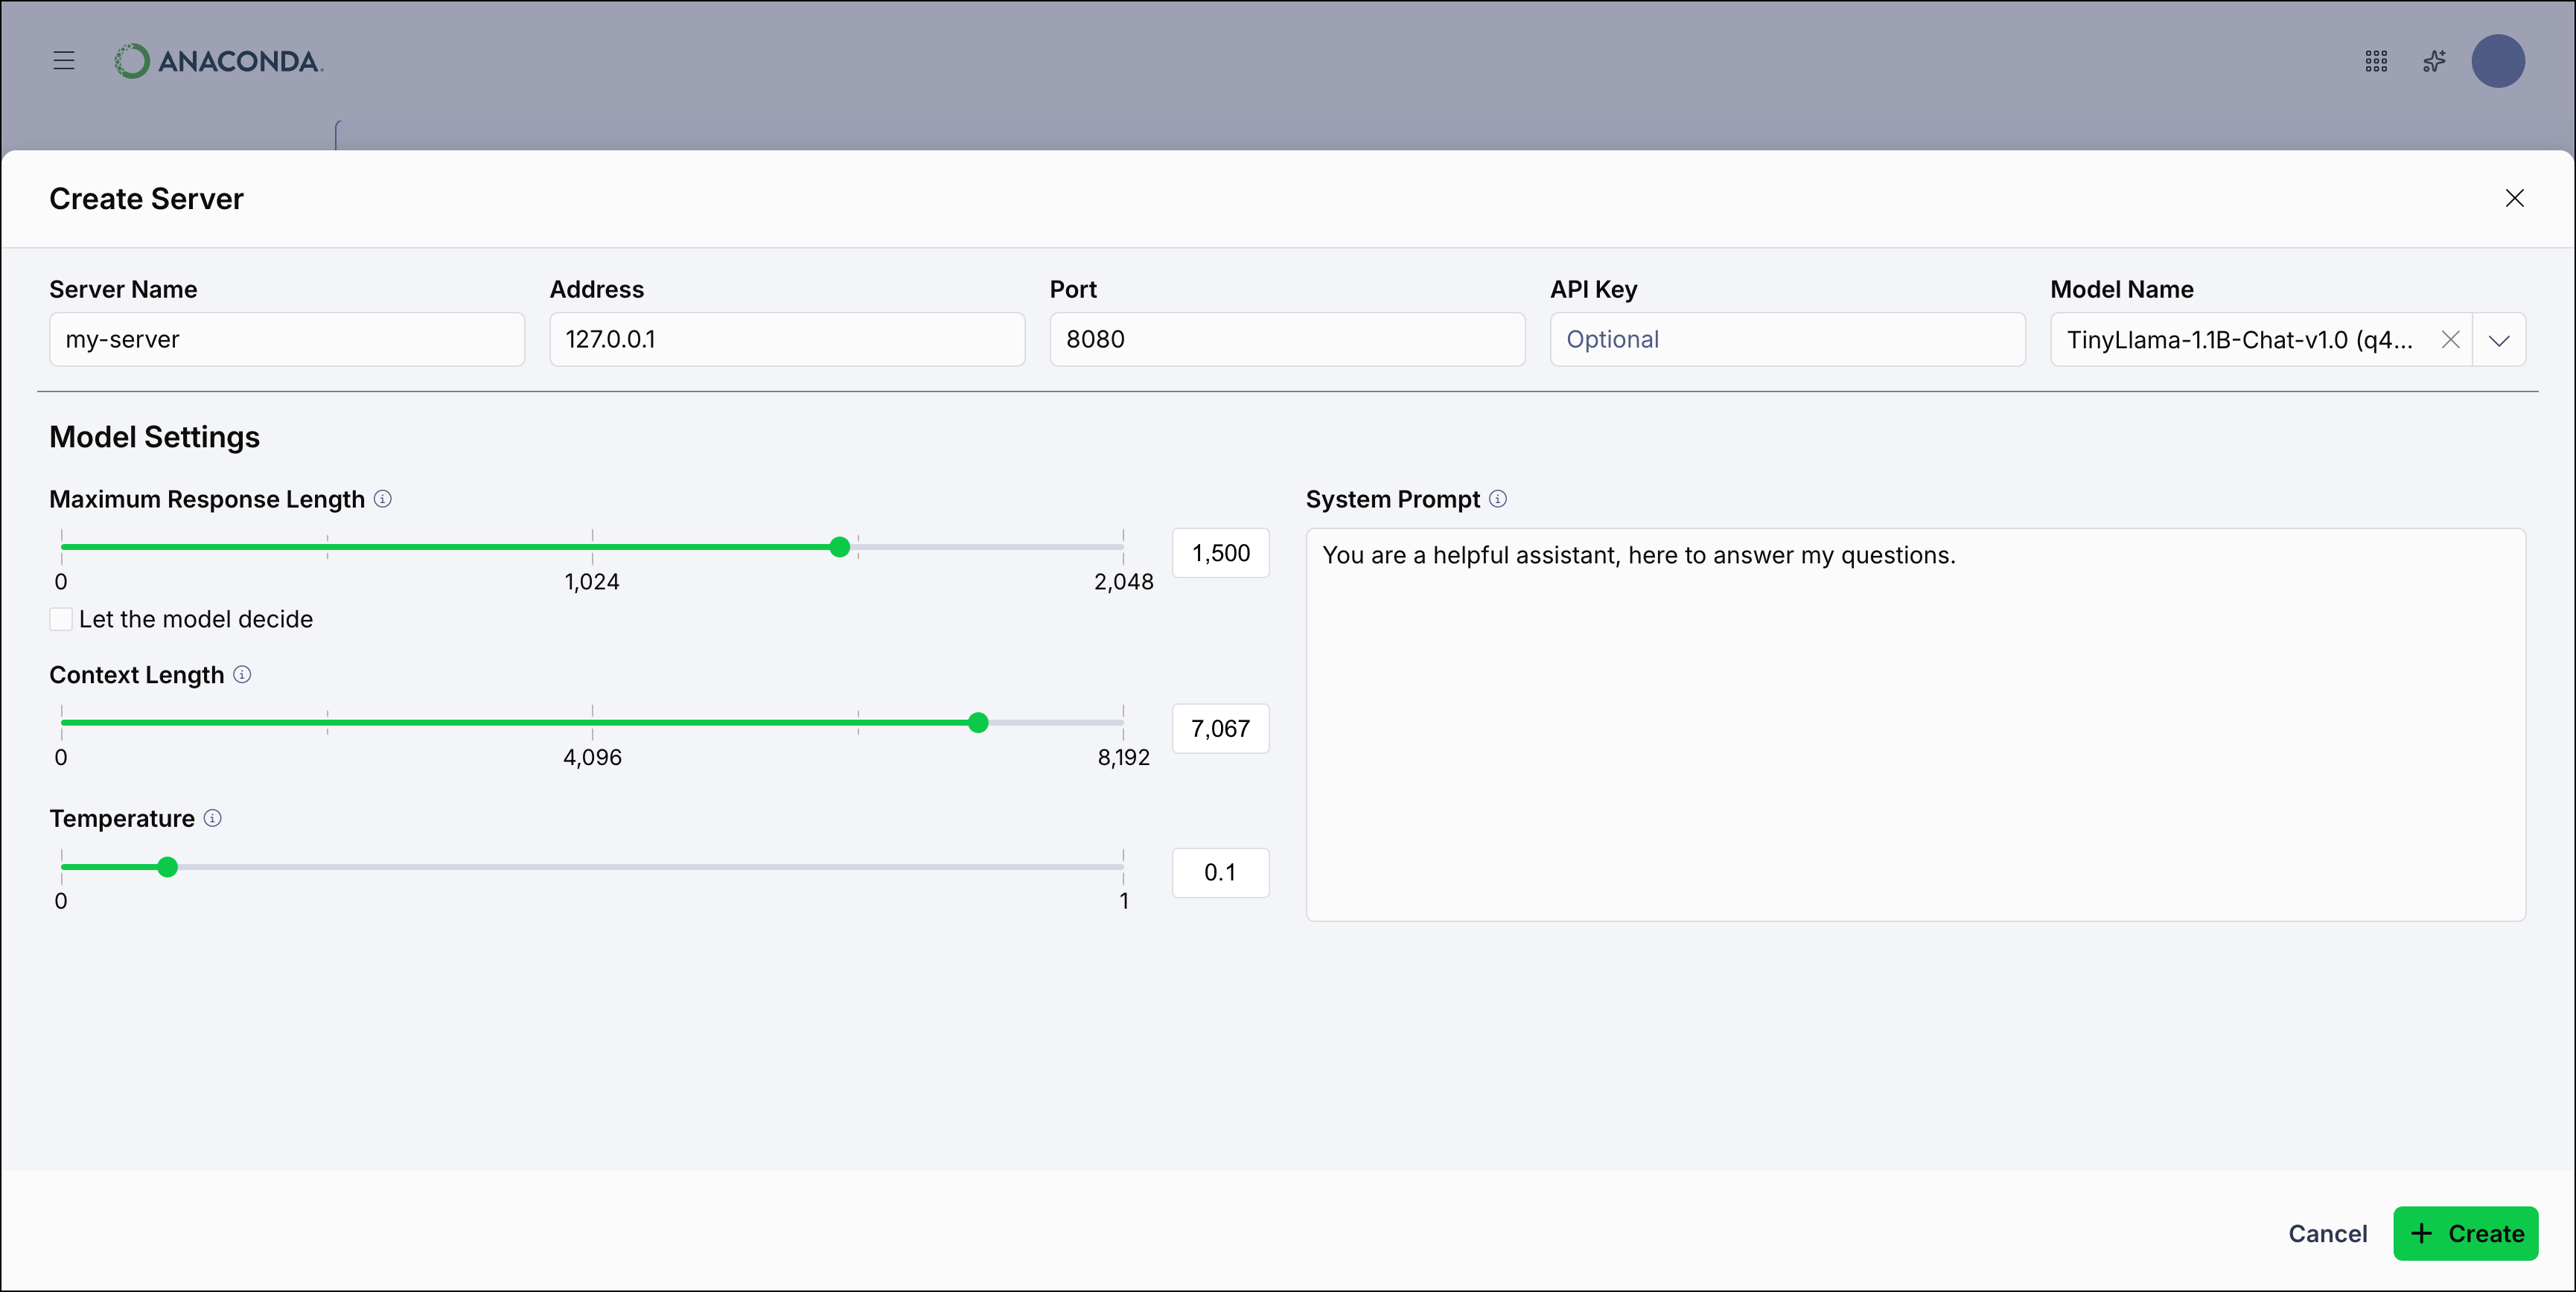 Click **Create**. The server appears in the **Servers** table.
### Model won't load (exit code 3221225781)
The model you are trying to load requires a C++ runtime environment, but Microsoft does not include one in their operating systems by default.
Install the Latest [Microsoft Visual C++ Redistributable Version](https://learn.microsoft.com/en-us/cpp/windows/latest-supported-vc-redist?view=msvc-170#latest-microsoft-visual-c-redistributable-version).
## Starting and stopping a server
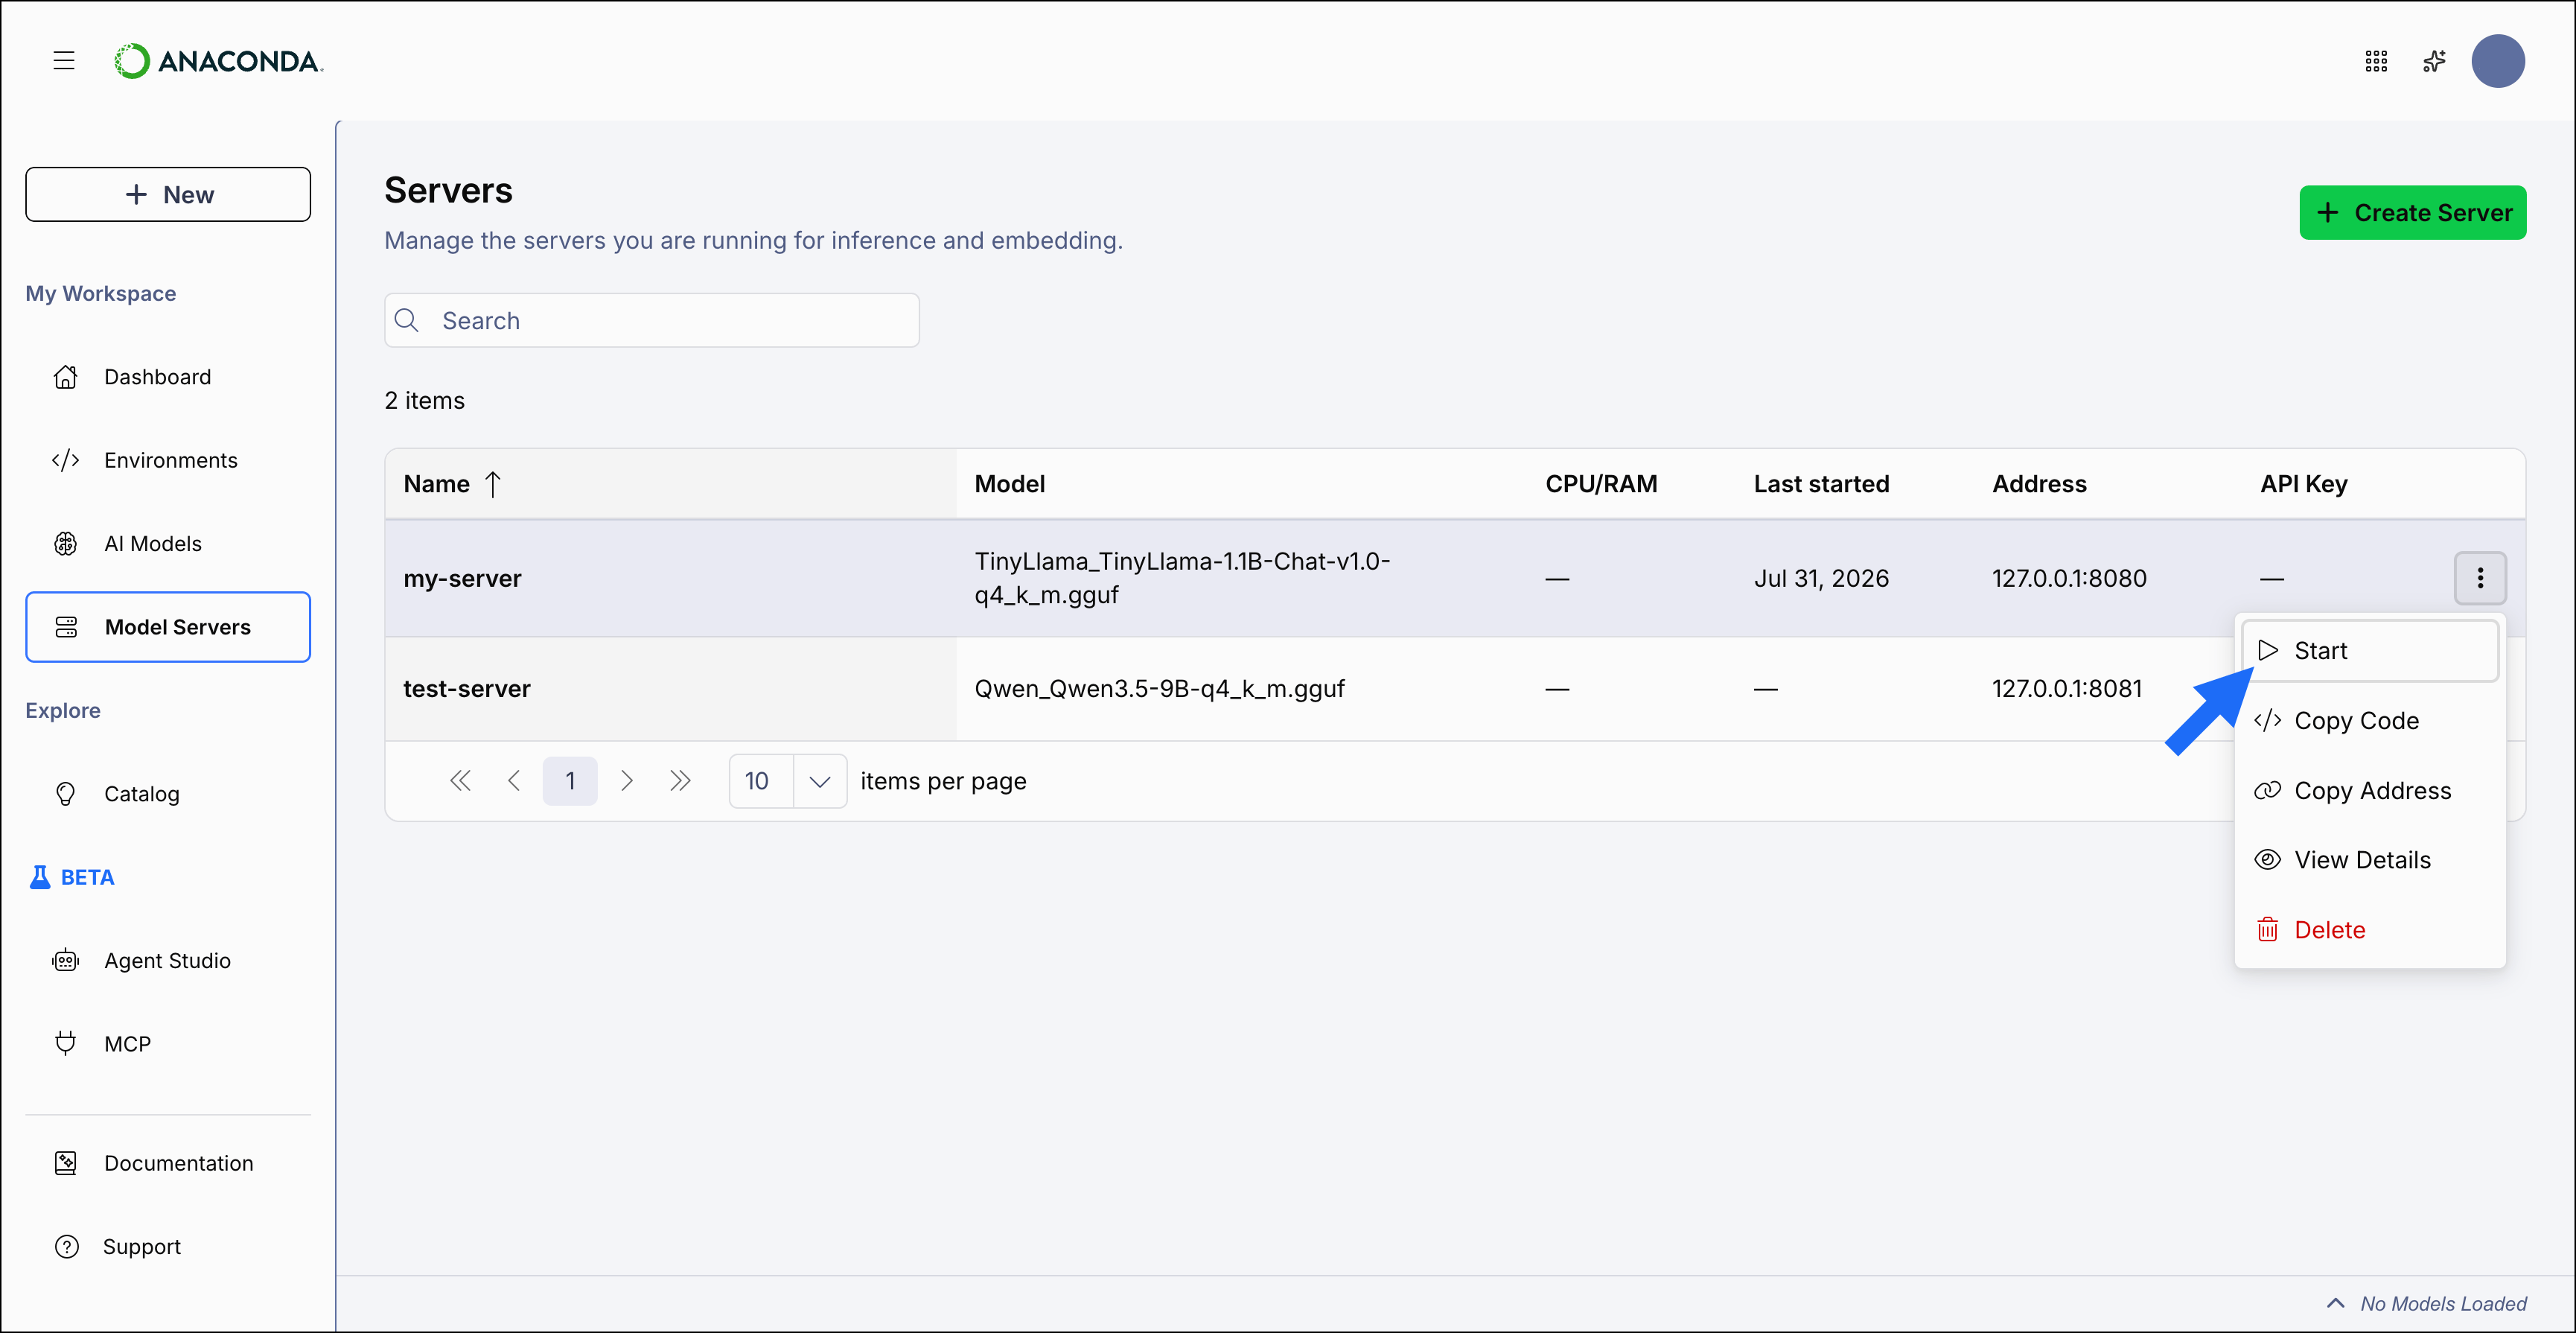
To start a server, click the actions menu on the server's row and select **Start**.
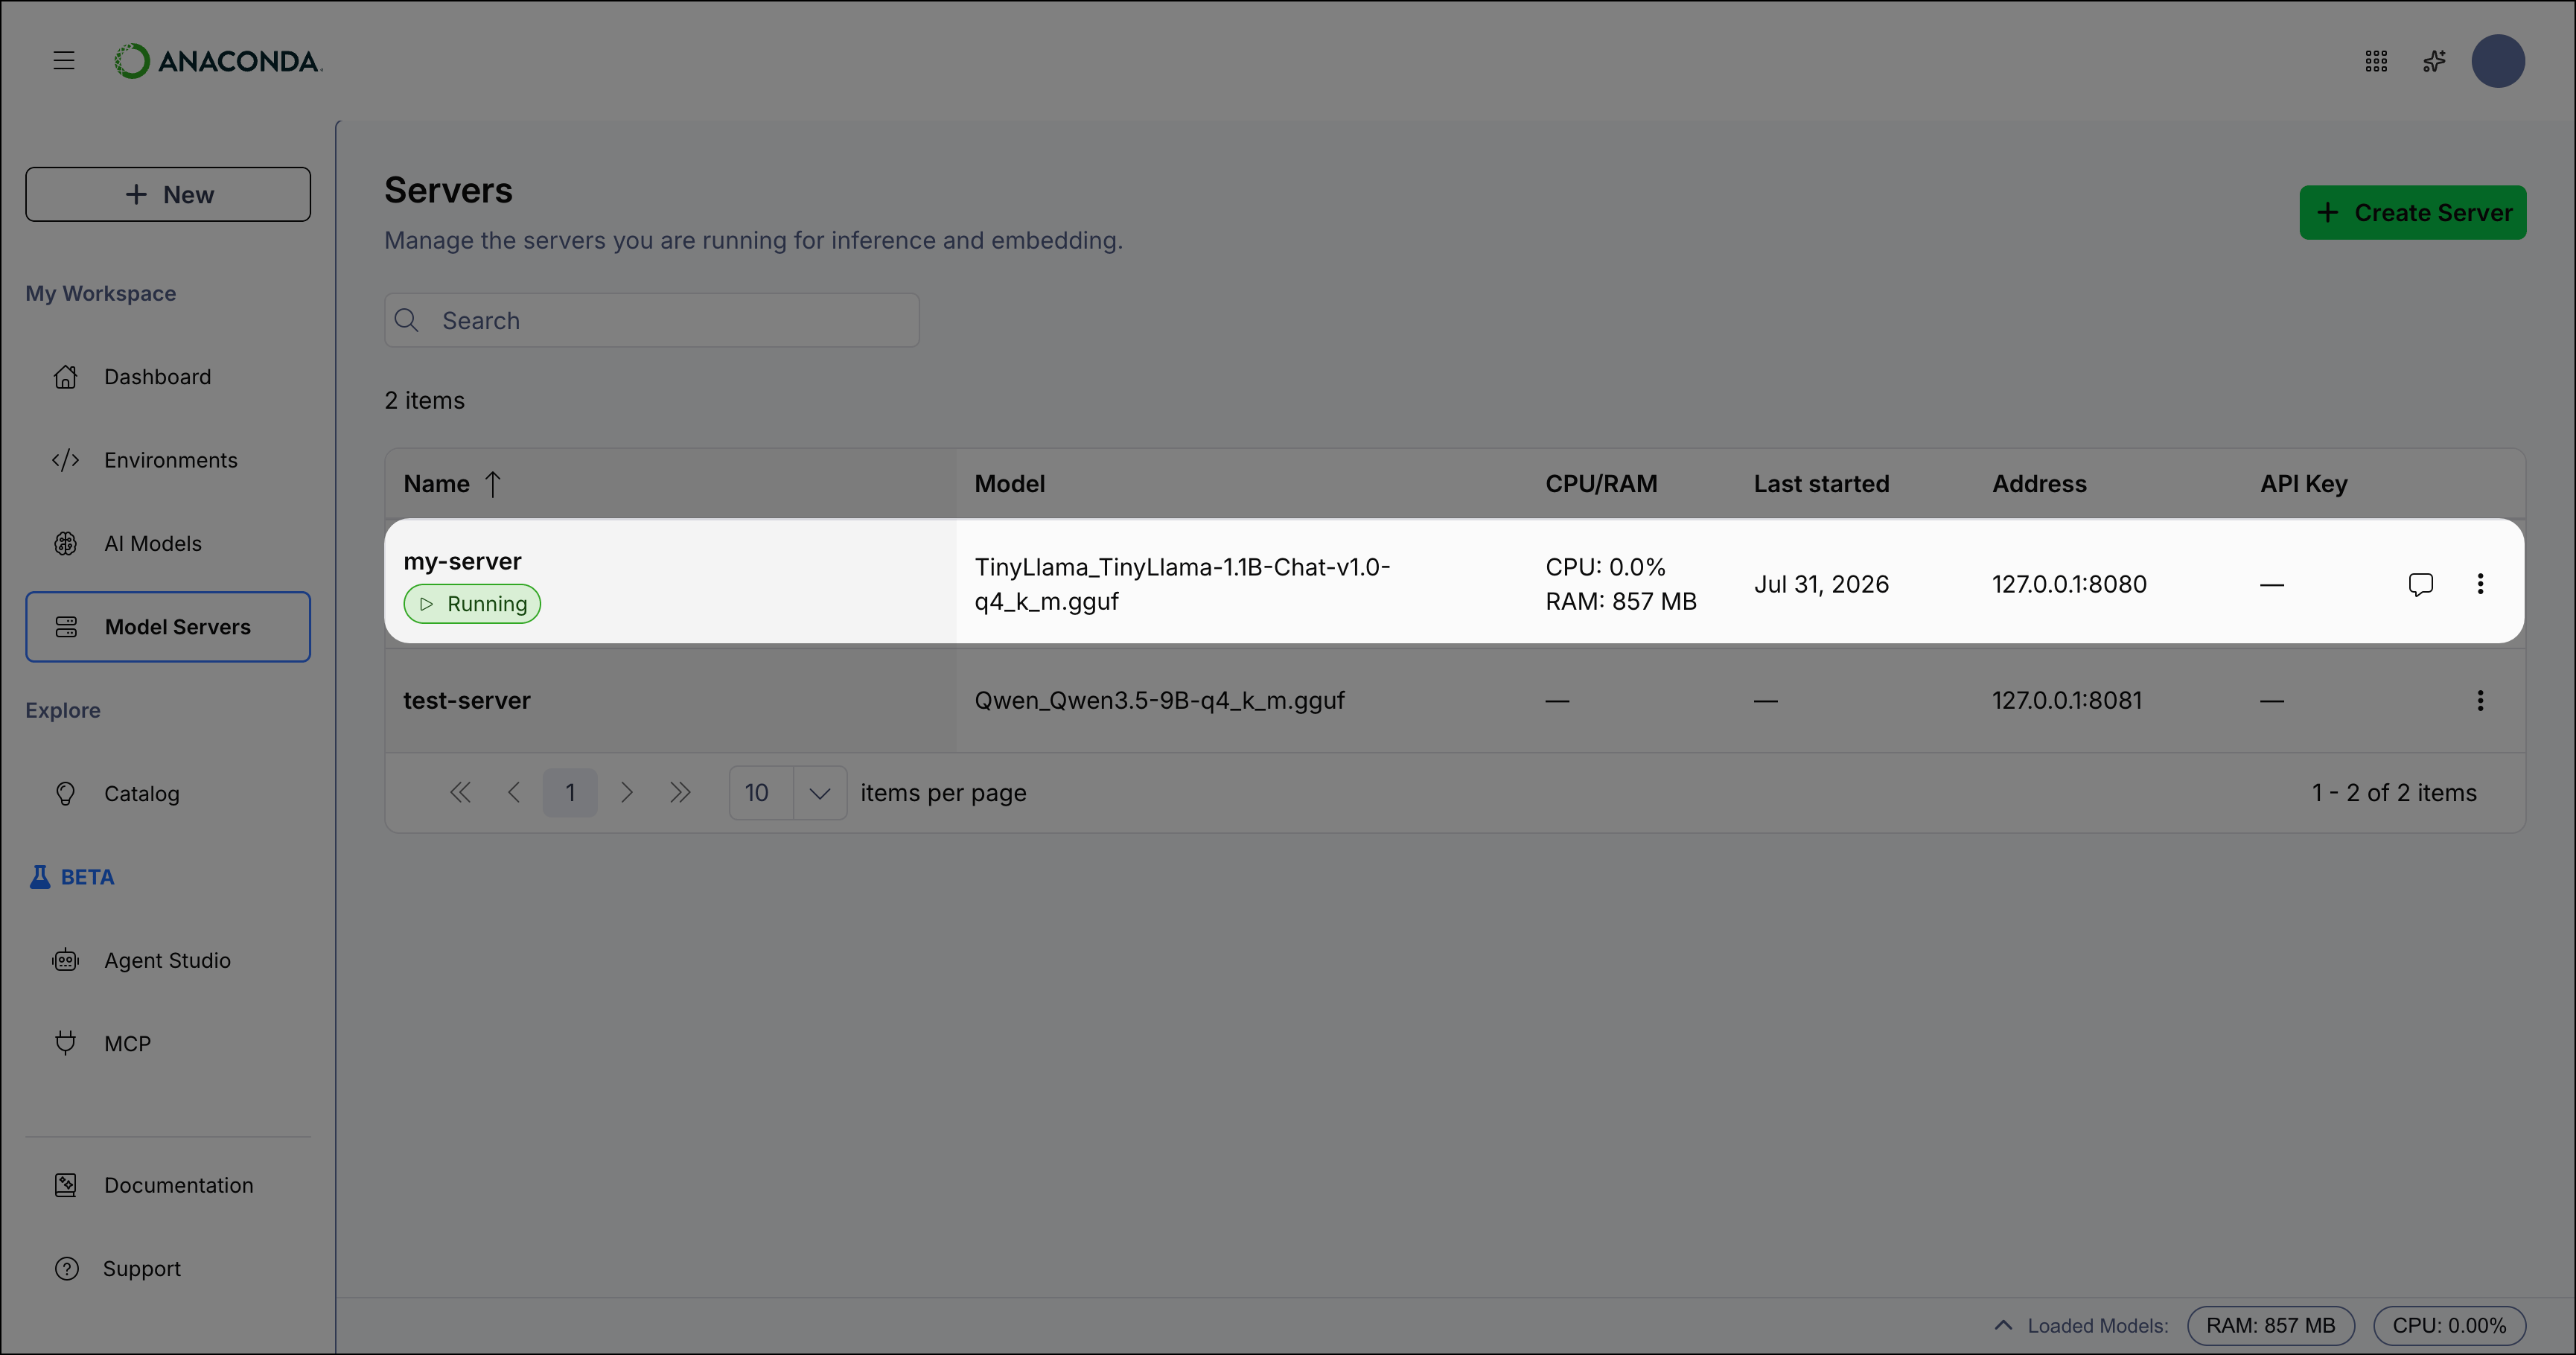
 The server's status updates to **Running** and live CPU/RAM usage appears in the row and in the status bar at the bottom of the page.
 To stop a running server, click the actions menu and select **Stop**.
## Viewing server details
Once you've created a server, you can view and edit its details. To open a server's details page, click the server's row on the **Servers** table or click the actions menu on the server's row and select **View Details**. The detail page has two tabs: **Overview** and **Logs**.
The **Overview** tab shows four cards:
* **Details**: The server's address, API key, model, and unique server ID. Hover over the **ID** or **Address** fields and click **Copy** to copy their values for use in API requests. Click **Edit** to modify the server configuration.
* **Code**: Ready-to-use connection code pre-filled with this server's address. The code varies by model and configuration. See [Connecting applications to servers](#connecting-applications-to-servers) for more information.
* **Model Settings**: The current values for Maximum Response Length, Context Length, Temperature, and System Prompt. Click **Edit** to update these settings.
* **Usage Metrics**: Current-session RAM and CPU usage for the running server. See [Resource consumption](/docs/anaconda-desktop/resource-consumption) for more information.
You must [stop the server](#starting-and-stopping-a-server) before editing its details or model settings.
The **Logs** tab shows the server log output. See [Viewing server logs](#viewing-server-logs) for details.
## Viewing server logs
The server records all incoming traffic and displays relevant information in the server logs. To view logs, open the server's [detail page](#viewing-server-details) and select the **Logs** tab.
The server logs record the following:
* **System information**: Provides information about your system's hardware capabilities.
* **Build information**: Provides information about the version of the server you are using.
* **Chat template**: Shows the sequence of messaging defined for the system.
* **Server listening**: Displays the server address and port number being listened to.
* **Slot information**: Displays the number of available slots for the server. Each slot is able to manage one user API request at a time.
* **Task information**: Displays information such as time spent processing and responding to a request, the request task ID, and which slot fulfilled the task.
After you stop the server, Desktop saves the log to the following location with a timestamped filename (for example, `_api-server.log`), so you can efficiently locate specific server logs, if necessary:
For Windows machines, you can find the logs here: `C:\Users\\AppData\Roaming\anaconda-desktop\logs`
For macOS machines, you can find the logs here: `~/Library/Logs/anaconda-desktop/`
## Understanding server settings
### Server address
Your local server address, often referred to as `localhost` or `127.0.0.1`, is the default address for model servers. It is a loopback address, meaning any network communication sent to this address remains within the same machine, keeping your data secure and private. This is common for developing applications.
`localhost` and `127.0.0.1` are semantically identical.
If you are working in an office network and want to make your server accessible to other devices within the same network, you can set the server address to your machine's local IP address. These are typically private networks, meaning they're not routable on the public internet.
Setting the server address to `0.0.0.0` configures it to accept connections on all network interfaces. This can expose your server to the public internet if your network is configured to allow external connections and route traffic from external sources to your server.
### Server port
The server port tells the model server where to listen for incoming traffic (that is, where to listen and pick up API requests).
For more information, see [Cloudflare's article on ports](https://www.cloudflare.com/learning/network-layer/what-is-a-computer-port/).
Your base URL for communicating with a server combines its address and port. For example, `http://127.0.0.1:8080/`. You can copy the URL directly from the **Address** column or by clicking the actions menu and selecting *Copy Address*.
### API key
An API key is an optional string that must be passed as an `Authorization: Bearer` token in the header of requests made to your server. You can choose any unique string as the API key, but the value you set when creating the server must match what you use in the `Authorization: Bearer` header.
To test an API key:
1. Select **Model Servers** from the left-hand navigation.
2. Enter your API key in the **API Key** field.
3. [Load a model into the API server](#creating-a-server).
You must use a `text-generation` type model.
4. Open Anaconda Prompt (Terminal on macOS/Linux) and run the following command:
```sh Anaconda Prompt theme={null}
curl --request POST ^
--url http://127.0.0.1:8080/completion ^
--header 'Authorization: Bearer ' ^
--header "Content-Type: application/json" ^
--data '{
"prompt": "Hello, how are you?"
}'
```
```sh Anaconda PowerShell Prompt theme={null}
curl --request POST `
--url http://127.0.0.1:8080/completion `
--header 'Authorization: Bearer ' `
--header "Content-Type: application/json" `
--data '{
"prompt": "Hello, how are you?"
}'
```
```sh Terminal theme={null}
curl --request POST \
--url http://127.0.0.1:8080/completion \
--header 'Authorization: Bearer ' \
--header "Content-Type: application/json" \
--data '{
"prompt": "Hello, how are you?"
}'
```
Replace \ with the API key you set when creating the server.
If you receive a response, your API key is working. If you receive a 401 error, double check your command or API key and try again.
## Connecting applications to servers
Connecting your application to a model server requires setting two environment variables: the `base_url`, which directs your API calls to the server hosting your model, and the `api_key`, which authenticates your requests.
Follow the steps below to find these variables' values and save them as environment variables in your application.
From the **Model Servers** page:
1. Note your **Server Address** and **Server Port** (the default is `http://localhost:8080`). This will be your `base_url`.
2. (Optional) Set an **API Key**. You can use any unique string value. If you don't set an API key, you don't need to provide an `api_key` in your application.
3. [Load a model](#creating-a-server) and click **Start**.
Set your credentials as environment variables:
```powershell Windows PowerShell theme={null}
$env:MODEL_SERVER_BASE_URL=""
$env:ANACONDA_API_KEY=""
```
```bash macOS/ Linux terminal theme={null}
export MODEL_SERVER_BASE_URL=""
export ANACONDA_API_KEY=""
```
Replace \ with the server address and port you copied from the **Model Servers** page.
Replace \ with the API key you created on the **Model Servers** page.
Setting environment variables is considered a best practice for security. However, for local testing and development, you can add the credentials directly in your code instead.
***
Environment variables set directly in the terminal will only last as long as the terminal session is active. To make these environment variables permanent, follow your system's standard process for persisting environment variables.
### OpenAI API compatibility
Anaconda Desktop model servers are OpenAI API compatible for chat completions. See OpenAI's [Chat Completion API documentation](https://developers.openai.com/api/reference/chat-completions/overview) for more information on making chat completion requests.
For production use, store the `base_url` and `api_key` values as environment variables rather than hardcoding them in your application.
See OpenAI's [Chat Completion API documentation](https://developers.openai.com/api/reference/chat-completions/overview) for more information on making chat completion requests.